# install.packages("tidyverse")
library(tidyverse)2 Data Exploration
Data analysis can generally be thought of as an iterative process consisting of four steps, which we will refer as the canonical data analysis workflow. Step one is data pre-processing, which involves transforming raw data into an analyzable form, including extracting structured data from unstructured sources such as text, images, or audio and preparing the resulting data for analysis. Step two is exploratory data analysis (EDA), which the act of examining and visualizing the observed data to develop intuition and identify potentially important features of the data. The third step is statistical learning, which seeks to identify meaningful structure in the data or uncover relationships among variables. In many of the following chapters, we introduce and apply common statistical learning models. Finally, the fourth step is interpretation, which involves considering what was learned through the analysis and what those findings mean in the context of the problem.
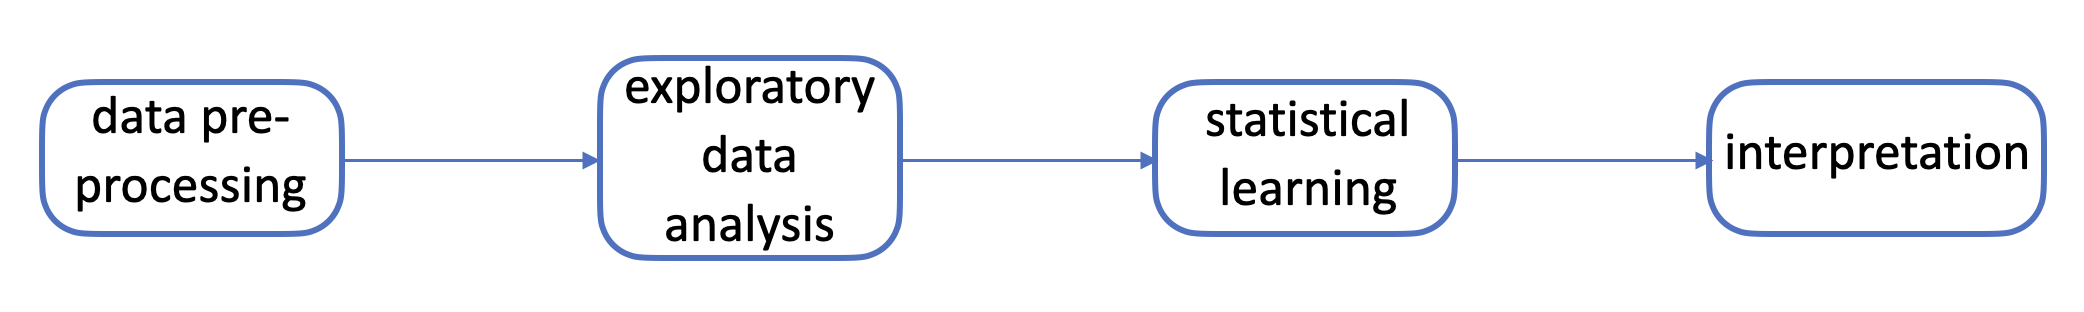
This chapter focuses on primarily on EDA, the second step of the canonical data analysis workflow. We begin by introducing how to import data into R and prepare it for analysis before explaining approaches for exploring and visualizing data. Although Figure 2.1 presents the workflow in a series of distinct steps, it is inherently iterative, as subsequent analyses may motivate further analyses and exploration. This ongoing process of exploration is part of what makes EDA so crucial.
2.1 Case Studies
Throughout this textbook, we will be exploring and applying statistical learning methods to a few different datasets. Here, we briefly discuss the background of each dataset and explore its structure.
Before we get started, let’s load the tidyverse package, which contains a collection of R packages designed with a similar structure in order to make data import, wrangling, and visualization intuitive and easy to learn. If you haven’t used this package before, be sure to uncomment the first line of code and install the package.
2.1.1 High School Test Scores
The high school dataset contains demographic and standardized test score information for 200 students. Demographic information includes the student’s sex (Gender) TODO: more inclusive name? and socioeconomic status (SES), both of which are categorical variables. We also have information on whether the student attends a public or private school (SchType), whether they are in a vocation, academic, or general program (ProgTyp), whether or not they are enrolled in their school’s honors program (HonorsProg), and how many awards they have won (Awards). In term of test scores, we are provided each student’s reading, writing, math, science, and social studies scores, which are scored on the TODO: X scale. Each student is identified by an ID, which is statistically uninformative. This data is comes from TODO: source.
scores <- read.csv("./data/hs.csv",stringsAsFactors=TRUE)
summary(scores)
ID Gender SES SchTyp ProgTyp
Min. : 1.00 female:109 high :58 private: 32 academic:105
1st Qu.: 50.75 male : 91 low :47 public :168 general : 45
Median :100.50 middle:95 vocation: 50
Mean :100.50
3rd Qu.:150.25
Max. :200.00
Reading Writing Math Science
Min. :28.00 Min. :31.00 Min. :33.00 Min. :26.00
1st Qu.:44.00 1st Qu.:45.75 1st Qu.:45.00 1st Qu.:44.00
Median :50.00 Median :54.00 Median :52.00 Median :53.00
Mean :52.23 Mean :52.77 Mean :52.65 Mean :51.85
3rd Qu.:60.00 3rd Qu.:60.00 3rd Qu.:59.00 3rd Qu.:58.00
Max. :76.00 Max. :67.00 Max. :75.00 Max. :74.00
SocStud HonorsProg Awards
Min. :26.00 enrolled : 53 Min. :0.00
1st Qu.:46.00 not enrolled:147 1st Qu.:0.00
Median :52.00 Median :1.00
Mean :52.41 Mean :1.67
3rd Qu.:61.00 3rd Qu.:2.00
Max. :71.00 Max. :7.00 2.1.2 Heart Disease Data
The heart disease dataset contains demographic and medical information on 270 patients, with the primary variable of interest being Disease, which is either absent or present. Demographic information includes patient Age and sex (Gender) TODO:rename, and general health variables are blood pressure (BP), whether or not the patient has a fasting blood sugar below TODO:check 120 mg/gL (FBS.120), and the patient’s total cholesterol in mg/dL (Chol). The remainder of the variables are more specific to heart disease, including the patient’s maximum heart rate (Max.HR), level of ST depression (ST.Dep) and ST slope (ST.Slope), TODO:vessels, thallium, ekg description (Num.Vessels), (Thallium), whether or not the patient has angina (Angina), the patient’s level of chest pain on a 1-4 scale (Chest.Pain), and (EKG).TODO: data source
heart <- read.csv("./data/heart_disease.csv",stringsAsFactors=TRUE)
summary(heart)
Age BP Chol Max.HR ST.Dep
Min. :29.00 Min. : 94.0 Min. :126.0 Min. : 71.0 Min. :0.00
1st Qu.:48.00 1st Qu.:120.0 1st Qu.:213.0 1st Qu.:133.0 1st Qu.:0.00
Median :55.00 Median :130.0 Median :245.0 Median :153.5 Median :0.80
Mean :54.43 Mean :131.3 Mean :249.7 Mean :149.7 Mean :1.05
3rd Qu.:61.00 3rd Qu.:140.0 3rd Qu.:280.0 3rd Qu.:166.0 3rd Qu.:1.60
Max. :77.00 Max. :200.0 Max. :564.0 Max. :202.0 Max. :6.20
ST.Slope Num.Vessels Thallium Gender Angina
Min. :1.000 Min. :0.0000 Min. :3.000 Female: 87 No :181
1st Qu.:1.000 1st Qu.:0.0000 1st Qu.:3.000 Male :183 Yes: 89
Median :2.000 Median :0.0000 Median :3.000
Mean :1.585 Mean :0.6704 Mean :4.696
3rd Qu.:2.000 3rd Qu.:1.0000 3rd Qu.:7.000
Max. :3.000 Max. :3.0000 Max. :7.000
Chest.Pain FBS.120 EKG Disease
Min. :1.000 No :230 Min. :0.000 Absent :150
1st Qu.:3.000 Yes: 40 1st Qu.:0.000 Present:120
Median :3.000 Median :2.000
Mean :3.174 Mean :1.022
3rd Qu.:4.000 3rd Qu.:2.000
Max. :4.000 Max. :2.000 2.1.3 Stellar Temperatures
The stellar temperatures dataset contains information on 10,000 measurements of stars. These measurements are collected from Gaia, a space-based telescope commissioned by the European Space Agency, which was in operatation from 2013 to 2025. In that time, Gaia made more than three trillion observations of two billion stars and other objects throughout our Milky Way galaxy and beyond, mapping their motions, luminosity, temperature, and composition. A portion of the data collected by Gaia was published in The Astronomical Journal in 2019 by Yu Bai et al., which is where this smaller subset of measurements is sourced from. We load the data TODO: from X and take a look at its structure.
stellar <- read.csv("./data/star_temps.csv")
glimpse(stellar)
Rows: 10,000
Columns: 11
$ Teff <dbl> 6112.170, 5172.570, 6121.700, 6265.820, 6717.410, 5325.570, 4…
$ RA <dbl> 239.74168, 39.76790, 143.60699, 118.55395, 291.55607, 170.595…
$ Dec <dbl> 23.181299, 36.764920, 9.224044, 16.165308, 39.224496, 19.9960…
$ Parallax <dbl> 1.3040, 3.6058, 1.1635, 0.9794, 1.6464, 0.6480, 3.0071, 0.545…
$ PM.RA <dbl> -7.268, 25.877, 10.092, -0.166, 5.901, -8.062, -36.817, -1.35…
$ PM.Dec <dbl> 2.029, -172.907, -10.563, -9.018, 0.276, -6.065, -0.097, 3.01…
$ g <dbl> 13.69551, 13.09189, 13.83536, 12.87293, 11.33363, 16.91027, 1…
$ b <dbl> 14.01445, 13.55505, 14.11267, 13.13956, 11.55238, 17.29075, 1…
$ r <dbl> 13.210281, 12.484341, 13.394859, 12.458502, 10.981853, 16.336…
$ Gal.L <dbl> 38.36613, 145.82831, 224.35701, 204.97085, 71.75512, 227.4524…
$ Gal.B <dbl> 47.619888, -21.275571, 40.278186, 20.988470, 10.608653, 68.42…This dataset has information on 11 variables from the 10,000 star measurements. Table 2.1 provides a codebook for this dataset.
stellar dataset.
| Variable Name | Description |
|---|---|
| Teff | Estimated surface temperature of the star |
| RA | Position of the star on the sky, measured east–west |
| Dec | Position of the star on the sky, measured north–south |
| Parallax | Apparent shift in the star's position used to estimate its distance from Earth |
| PM.RA | How quickly the star moves across the sky in the east–west direction |
| PM.Dec | How quickly the star moves across the sky in the north–south direction |
| g | Brightness of the star measured in a green/visual-light band |
| b | Brightness of the star measured in a blue-light band |
| r | Brightness of the star measured in a red-light band |
| Gal.L | Position of the star within the Milky Way, measured around the Galactic plane |
| Gal.B | Position of the star above or below the Galactic plane |
2.2 Importing Data
The first step of the canonical data analysis workflow, displayed in Figure 2.1, is data-preprocessing. In this chapter, we will not discuss methods for converting raw data—such as text or images—into an analyzable form. Instead, we will review how to import tidy data into R and, in Section 2.3, how to manipulate it into a format suitable for your intended analysis. Tidy data provide a consistent organizational framework in which each variable is represented by a column, each observation is represented by a row, and each type of observational unit is represented by a separate data table.
While data can sometimes be imported from a webpage or through an R package, data is most commonly downloaded onto your computer and imported locally. When downloading data, it is best practice to store your data in either the same folder or a subfolder of the location of your script, as opposed to the Downloads folder. This allows for the use of relative paths instead of absolute paths, which makes collaboration much easier.
After downloading the data, open your script in RStudio/Positron and check your working directory by typing getwd() in the console. Does the listed file path match where your script is located? If needed, change the working directory by using setwd().
Now we can write code to import the data. Below, we import the high school test scores dataset (hs.csv), which is located in the data subfolder of our working directory. This can be done using read.csv().
hs <- read.csv("data/hs.csv", stringsAsFactors=TRUE)read.csv() takes a number of optional arguments. stringAsFactors=TRUE converts character strings (text) into factors when importing the data frame. In the high school test scores data, there are several categorical variables that take a small number of values (e.g. school type, program type, honors program). Treating these variables as factors is good practice in downstream analyses. Other optional arguments include header, which can be set to TRUE if the file contains the names of the variables as its first line, and sep, which allows delimiters other than comma, such as semicolon, tab, or pipe. Type ?read.csv to see more optional arugments that may prove useful, especially when importing large or messy data.
Alternative file formats (e.g. .rds, .xlsx, .dta) can be imported using other functions, such as readRDS(), readxl::read_xlsx(), or haven::read_dta(). While these have their own optional arguments, the key step of specifying the correct file path to the data is the same.
2.3 Data Wrangling and Exploration
Data rarely come structured exactly as we need to carry out our analysis plan. Often, we need to clean data, create new variables, reshape data, or summarize observations before we can dive into data visualization or modeling. In this section, we introduce what are commonly referred to as the six main verbs of dplyr, which are used to carry out many data wrangling and exploratory data analysis tasks. We also introduce how to pivot data frames and join multiple data frames together.
Before that, however, we must first introduce the pipe operator (|>). The pipe operator, or pipe for short, chains multiple functions together in a sequential, readable order. It works by taking the output of the function on its left and passing that into the first argument to the function on its right. For example, the following code says to combine the six values into one vector, remove any duplicate elements (here, the repeated values of 3 and 4), and return the length of the vector.
c(1, 2, 3, 3, 4, 4)|>
  unique() |>
  length()
[1] 4Pipes make our code easy to read and debug. We can easily add or remove functions from the pipeline or simply run the code through an intermediary step. We will work up to using pipes to chain together multiple calls of the six main verbs.
2.3.1 The six main verbs of dplyr
2.3.1.1 select
The first function we will cover is select, which is used to state which variables to keep in our dataset. For instance, perhaps we are working with the scores dataset and want a dataset without any demographic information that solely gives the raw scores. We’d do this as follows.
scores |>
  select(Reading, Writing, Math, Science, SocStud)
Reading Writing Math Science SocStud
1 34 35 41 29 26
2 34 33 41 36 36
3 39 39 44 26 42
4 37 37 42 33 32
<snipped 196 lines>We can also use select to remove variables that we don’t want. For instance, perhaps we want to retain all the information in the dataset except for the student identifier, gender, and socioeconomic status. We can do this with select(-column_name), or put multiple column names in a vector, as shown below.
scores |>
  select(-c(ID, Gender, SES))
SchTyp ProgTyp Reading Writing Math Science SocStud HonorsProg Awards
1 public vocation 34 35 41 29 26 not enrolled 0
2 public general 34 33 41 36 36 not enrolled 0
3 public vocation 39 39 44 26 42 not enrolled 0
4 public vocation 37 37 42 33 32 not enrolled 0
<snipped 196 lines>2.3.1.2 filter
Similar to select, filter is also used to obtain a subset of the data. However, filter removes observations (rows), while select retains a subset of variables (columns). As an example, we may want to learn more about students that went to an adademic program. Notice that we use “==” to mean “equal to”. This is not saying “assign the program type to be academic”, but rather, “only keep rows where the program type is equal to academic”.
scores |>
  filter(ProgTyp == "academic")
ID Gender SES SchTyp ProgTyp Reading Writing Math Science SocStud
1 128 male high public academic 39 33 38 47 41
2 11 male middle public academic 34 46 45 39 36
3 43 female low public academic 47 37 43 42 46
4 196 male high private academic 44 38 49 39 46
<snipped 207 lines>We can also filter on multiple condtions. For instance, we may want to filter for students enrolled in the honors program in academic program.
scores |>
  filter(ProgTyp == "academic" & HonorsProg == "enrolled")
ID Gender SES SchTyp ProgTyp Reading Writing Math Science SocStud
1 147 female low public academic 47 62 53 53 61
2 159 male high public academic 55 61 54 49 61
3 79 female middle public academic 60 62 49 50 51
4 179 female middle private academic 47 65 60 50 56
<snipped 77 lines>2.3.1.3 mutate
Our third verb, mutate, is used to create new variables or make changes to existing ones. For example, we may want to create a new variable, stem_score, that gives a student’s total score between math and science.
scores |>
  mutate(stem_score = Math + Science)
ID Gender SES SchTyp ProgTyp Reading Writing Math Science SocStud
1 45 female low public vocation 34 35 41 29 26
2 108 male middle public general 34 33 41 36 36
3 15 male high public vocation 39 39 44 26 42
4 67 male low public vocation 37 37 42 33 32
<snipped 397 lines>A common verb that mutate is used with is case_when(), which evaluates each case sequentially and uses the first match for each observation to determine the corresponding value in the output vector. For example, perhaps we want to create a categorical variable, awards_cat for the number of awards a student has won.
scores |>
  mutate(awards_cat = case_when(Awards == 0 ~ "none",
                                Awards %in% c(1, 2) ~ "1-2",
                                Awards >= 3 ~ "3+"))
ID Gender SES SchTyp ProgTyp Reading Writing Math Science SocStud
1 45 female low public vocation 34 35 41 29 26
2 108 male middle public general 34 33 41 36 36
3 15 male high public vocation 39 39 44 26 42
4 67 male low public vocation 37 37 42 33 32
<snipped 397 lines>Another very common use of mutate is for changing the type of a variable. For example, because ID does not represent a practically meaningful value, we may want to change it to be a factor instead of a numeric variable. Functions as.integer, as.numeric, or as.character are a few other commonly used functions with mutate to change to variable type.
scores |>
  mutate(ID = as.factor(ID))
ID Gender SES SchTyp ProgTyp Reading Writing Math Science SocStud
1 45 female low public vocation 34 35 41 29 26
2 108 male middle public general 34 33 41 36 36
3 15 male high public vocation 39 39 44 26 42
4 67 male low public vocation 37 37 42 33 32
<snipped 397 lines>2.3.1.4 arrange
Our fourth verb, arrange, orders the rows of a dataset by the values of selected columns. For example, we may want to order scores by Reading score, and secondarily by Writing score.
scores |>
 arrange(Reading, Writing)
ID Gender SES SchTyp ProgTyp Reading Writing Math Science SocStud
1 19 female low public general 28 46 43 44 51
2 164 male middle public vocation 31 36 46 39 46
3 108 male middle public general 34 33 41 36 36
4 45 female low public vocation 34 35 41 29 26
<snipped 397 lines>We can also order the dataset in descending order using arrange with desc. For example, we may want to arrange the students by number of Awards won, from largest to smallest.
scores |>
  arrange(desc(Awards))
ID Gender SES SchTyp ProgTyp Reading Writing Math Science SocStud
1 92 female high public general 52 67 57 63 61
2 32 female high public vocation 50 67 66 66 56
3 59 female middle public academic 65 67 63 55 71
4 93 female high public academic 73 67 62 58 66
<snipped 397 lines>2.3.1.5 group_by
If we want to calculate statistics within different groups in the data, we use group_by. For instance, we may want to analyze test scores by school type (SchTyp) in order to understand if there are differences in performance between students in our dataset from public and private schools.
scores |>
  group_by(SchTyp)
# A tibble: 200 × 12
# Groups: SchTyp [2]
ID Gender SES SchTyp ProgTyp Reading Writing Math Science SocStud
<int> <fct> <fct> <fct> <fct> <int> <int> <int> <int> <int>
1 45 female low public vocation 34 35 41 29 26
<snipped 11 lines>In the output above, note that nothing has changed. However, there is now a line of output Groups: SchTyp [2], which communicates that our data is now grouped by the SchTyp variable, which takes two values. In order to calculate ststistics by group, we typically use group_by with summarize, our final verb.
2.3.1.6 summarize
The most frequent companion of group_by is summarize, which returns one row for each level of the grouping variable. If there are multiple grouping variables, it returns a row for every combination of grouping variables. We can now calculate the mean Reading and Writing score for students in our dataset from public and private schools.
scores |>
  group_by(SchTyp) |>
  summarize(avg_reading = mean(Reading), avg_writing = mean(Writing))
# A tibble: 2 × 3
SchTyp avg_reading avg_writing
<fct> <dbl> <dbl>
1 private 54.2 55.5
2 public 51.8 52.2The summarize function can also used with no grouping variables, in which case it will summarize across all observations. For instance, we can calculate the maximum reading and writing scores in the dataset.
scores |>
  summarize(avg_reading = max(Reading), avg_writing = max(Writing))
avg_reading avg_writing
1 76 672.3.2 Pivoting
Datasets sometimes do not come organized in a way convinient for us to analyze, and we may have to pivot the data to a different orientation as a result. For example, the test scores data is structured where a student’s score on each subject is given in a separate column. Instead, we may prefer there to be one column called subject and one column called score. In this longer format, there are multiple rows for each student, and fewer columns. With the data in this format, it can be easier to visualize the distribution of scores from multiple subjects at once, something we discuss more in Section TODO: ADD section number.
Let’s walk through the code to do this pivot. As a reminder, below is current structure of our data, subset to the relevant columns using select. We see each row represents one student.
hs |>
  select(ID, Reading:SocStud)
ID Reading Writing Math Science SocStud
1 45 34 35 41 29 26
2 108 34 33 41 36 36
3 15 39 39 44 26 42
4 67 37 37 42 33 32
<snipped 196 lines>To pivot the data frame to a longer format, we use pivot_longer, which takes three key arguments. The cols arugment takes the vector of the column names that we intend to pivot into the longer format: here, those are the different subjects. The names_to argument specifies the new column to create that will contain the variable names of the columns in cols. Because each column being pivoted is a school subject, we call this "Subject". Finally, the values_to arugment species the name of the column to create from the data stored in cell values. Below, we see that the pivoted data frame now has 1,000 rows instead of only 200, as each student has five rows.
scores_long <- hs |>
  select(ID, Reading:SocStud) |>
  pivot_longer(cols = Reading:SocStud, names_to = "Subject", values_to = "Score")

scores_long
# A tibble: 1,000 × 3
ID Subject Score
<int> <chr> <int>
1 45 Reading 34
2 45 Writing 35
3 45 Math 41
4 45 Science 29
5 45 SocStud 26
6 108 Reading 34
7 108 Writing 33
<snipped 4 lines>We can pivot the above dataset back to the original wide format using pivot_wider. Again, we have three key arguments. The first argument, id_cols, is an optional argument that takes a set of column(s) that uniquely idenify each observation. In the hs dataset, ID is a sole unique identifier. The code below can be run without the id_cols argument: when left empty, it defaults to all columns in data except for the columns specified through names_from and values_from. However, it is good practice to include this argument to make sure your each row in your output is uniquely and predictably identified. The second argument, names_from, specifies which column to get the name of the output columns, and the third argument, values_from, indicates which column to get the cell values from.
scores_long |>
  pivot_wider(id_cols = ID, names_from = Subject, values_from = Score)
# A tibble: 200 × 6
ID Reading Writing Math Science SocStud
<int> <int> <int> <int> <int> <int>
1 45 34 35 41 29 26
2 108 34 33 41 36 36
3 15 39 39 44 26 42
4 67 37 37 42 33 32
5 153 39 31 40 39 51
6 51 42 36 42 31 39
7 164 31 36 46 39 46
<snipped 4 lines>2.3.3 Joining
All the data that we need to answer a given question rarely lives in a single file. Instead, we may pull data from several different sources or from a database, which is a structured, electronic collection of data. As a result, we need skills to join datasets together.
The type of join that we perform will depend on our goals and context. There are two main types of joins: mutating joins and filtering joins. The goals of these joins align with the goals of the functions mutate and filter: mutating joins add new columns to the data frame, while filtering joins retain or remove rows from your data frame.
2.4 Missing Data
In any given structured data table, there may be cells that are empty. These cells indicate data that are missing. For instance, perhaps we are trying to import the comma-separated-value file assigned to txt. The second element of the first row is missing, as is the first element of the second row. R, for instance, can still read this table, with NA (for Not Available) inserted as the data values.
txt <- "x,y,z
        1,,1
        ,2,2
        3,3,-99"

df <- read.csv(text = txt, colClasses = "numeric")
df
x y z
1 1 NA 1
2 NA 2 2
3 3 3 -99It is important to note, however, that missing data are not always represented by empty table cells. For instance, as shown in df above, the person collecting the data may elect to use a particular value (like -99) to indicate missingness (and, perhaps, not document that choice!). We should always be careful to examine data during exploratory data analysis to see if there are particular values that appear strange (and perhaps over-represented). We can always convert these values to NA as we need to, as demonstrated in the code below.
df[df==-99]<-NA
df
x y z
1 1 NA 1
2 NA 2 2
3 3 3 NAAdditionally, missing values in imported data may not truly be missing. For example, in the names dataset below, it is likely fair to assume that Mia is an only child, meaning we can replace NA with 0.
names <- read.csv(text = txt, colClasses = c("factor", "integer"))
names
name siblings
1 Fred 2
2 Joanna 1
3 Mia NA
4 Mateo 3
5 Kai 1names <- names %>%
dplyr::mutate(siblings = tidyr::replace_na(siblings, 0))The short explanation of why missing data matter is that statistical learning algorithms cannot run if there are missing table entries. Any observations with a missing value for a variable that is part of the algorithm will be omitted entirely. The picture below represents two measurements, \(x_1\) and \(x_2\), made for 12 objects. Both measurements are observed for 10 of the 12 objects. However, for one object, \(x_1\) is known, but \(x_2\) is missing. The value of \(x_2\) can therefore lie anywhere along the vertical orange line. Statistical learning algorithms will not “guess” where that \(x_2\) datum is to go.

To solve the issue of missing data and complete downstream analyses, we have two options. The first is to remove rows and/or columns with missing data from the dataset prior to analyses. The second is to attempt to impute the missing data.
2.4.0.1 Removing data
Removal of data prior to analysis can be tricky in that there is no simple recipe to follow. For instance, say all the missing data in our dataset come from one variable. We might be tempted to remove that variable from our analysis. However, if the number of missing values in that variable is small, we might be tempted to simply remove those observations with missing data and retain the rest of the observations with complete data.
TODO: Paragraph on MCAR, MAR, MNAR
There are two primary considerations to keep in mind when trying to decide between removing observations versus removing variables:
- When we remove observations, we reduce the overall sample size. This impacts the level of uncertainty in estimation. For example, if we are trying to estimate an average, recall that the variance of the mean is \(V[\bar{X}] = \sigma^2/n\), where \(\sigma^2\) is the population mean and \(n\) is the number of observations. The smaller the \(n\), the larger our variance, and the more uncertain we are about \(\bar{X}\).
- When we remove variables, we may greatly impact the ability of any learned statistical model to make predictions. Or we may not. For instance, if we are trying to predict hospital costs for patients, removing the variable
genderwill have less of an impact on our accuracy than removing the variableage.
If the number of observations with missing data is relatively small, the safest initial approach is to remove those observations and proceed, regardless of the proportion of the variables for which the data are actually missing. But, if we have sufficient time and resources, we should always explore a variety of approaches. For instance, we could take out the observations with missing data and do an analysis and then separately only take out the variables with missing data and do an analysis. We could then compare the predictive abilities of the models.
2.4.0.2 Data imputation
Instead of removing data, we may also consider data imputation. Data imputation means using the known values in our dataset and background knowledge to estimate the missing data values. For instance, given our schematic picture of missingness above, we might think that, yes, there are certain regimes along the vertical and horizontal green lines where it would be more probable to observe data than others. Imputation is simply turning that intuition into an algorithm. However…
The idea of imputation is both seductive and dangerous. It is seductive because
it can lull the user into the pleasurable state of believing that the data are
complete after all, and it is dangerous because it lumps together situations
where the problem is sufficiently minor that it can be legitimately handled [via
imputation] and situations where standard estimators applied to the real and
imputed data have substantial biases.

- Dempster & Rubin (1983)
In other words, how do we know that we’ve put the data in “good places”, and how do we know that our attempt at imputation might not simply lead us down the road to biased results? Several procedures have been developed with the intent of avoiding biased results. As with most procedures, there are easy (but sub-optimal) approaches and more principled (but more computationally intensive) approaches.
The simplest approach of all is to determine the sample mean or median of the known data for the variable and use that value. The pro of this approach is that it is easy to implement and explain, while the con is that the imputed data are not distributed as the known data are. Instead, they only take one value.
To improve this approach, we could use a method known as hot-deck imputation. Let’s say that we have data on United States counties, but that the county’s unemployment rate is missing in some observations. With hot-deck imputation, we’d take an observation missing unemployment rate, look for the counties in our dataset with similar characteristics (e.g. similar population density, population size, region of county), pick of one of those counties, and then use that county’s unemployment rate as the imputed value. The way we pick which county can either be deterministic (the county with the closest matching attributes) or random (draw a random sample from the subset of counties with similar records). The approach is known as hot-deck imputation because hot refers to using the current dataset, as opposed to cold-deck, which relies on external data sources. The term deck comes from the idea of a deck of cards, where each “card” represents an observation (such as a county), and missing values are filled by drawing from similar observations within that deck.
While there are many more imputation alogorithms for various types of data, the last we will introduce here is Multiple Imputation by Chained Equations (MICE). The MICE procedure imputes missing values in a dataset through an iterative series of predictive models, where in each iteration, missing values for one variable are predicted using values from other variables in the dataset. Suppose we have a dataset with three variables (A, B, and C). The steps to perform MICE are as follows, and can also be implemented with the mice R package:
Choose the number of iterations k you will perform: Using five to ten iterations often works well in practice.
Initialize missing values: For each variable, temporarily replace the missing values with the mean or median of the observed values. At this stage, there are no missing values in the dataset.
Select a target variable for imputation: For variable
A, for instance, change the imputed values back to missing.Fit an imputation model: Regress
Aon the other variables (BandC), using only the rows where A is observed. Then use this model to predict and impute the missing values inA.Repeat steps 3-4 for variables
BandCas well, using the newly predicted values forA.
These are the steps for one of the k iterations. Each iteration begins using the dataset produced at the end of the previous iteration, which is where the chained part of the name comes from. With each iteration, the predicted values improve until some convergence point. MICE can be implemented not only for continuous variables, but also for binary, unordered categorical, and ordered categorical variables. We should, however, keep in mind that MICE requires the data to be missing at random. Additionally, the effectiveness of the method may wane with increased levels of missingness or at smaller sample sizes.
2.5 Exploratory Data Analysis
Exploratory Data Analysis (EDA) is the act of building intuition about observed data through visualization and statistical summaries. It is a critical component of any data analysis. Sometimes, research questions can be answered from EDA alone. For example, a histogram of exam scores can tell the professor how their class performed and whether a curve should be applied—no statistical learning model is needed. Oftentimes, however, EDA serves as a foundation for subsequent modeling and inference. Even when it is not sufficient to fully answer a research question, EDA is a necessary step in the data analysis process. In the words of American mathematician and statistician John Tukey,
The greatest value of a picture is when it forces us to
notice what we never expected to see.
EDA can reveal outliers, identify potential errors in the data, guide the selection of appropriate statistical learning methods, inform variable selection for predictive modeling, and generate hypotheses about relationships within the data. Jumping directly into modeling without first understanding the data can lead to misleading conclusions and poorly chosen methods.
So, if EDA is so important, how do we go about it? EDA is more of an art than a science. There is no single correct procedure, and the exact process will vary depending on our research goals and the nature of the data being analyzed. Nevertheless, we can outline a general framework that can be adapted to a wide range of scientific questions and applications. The steps are as follows:
- Understand how the data is structured. Explore simple questions like:
- How many variables and observations are there?
- What are the variable types (e.g. numeric, categorical, date, logical)? Do we need to manually correct any of these types?
- Understand relevant variables individually. Univariate visualizations and summaries help us explore the typical values that a variable will take. For each relevant variable, we recommmend creating summaries or graphs to answer questions such as:
- For continuous variables: How is the variable distributed—unimodally or bimodally? Is it symmetric or skewed? What are the mix/max values for this variable, and do they seem reasonable?
- For categorical variables: How many different values does this variable take? Are certain values more prevalent than others? Is than an unordered or ordered categorical variable?
- Is this variable uninformative (e.g. a columns of 1’s) or does it take different values than we might expect?
- Does the variable contain any missing values? If so, how many?
- Explore relationships between variables. This step is particularly helpful for choosing an appropriate statistical learning model. Explore questions including:
- Is there a visually apparently association between each relevant predictor variable and the response? Is this relationship linear or nonlinear? Strong or weak?
- Are any of the predictor variables correlated with one another? If so, are they strongly correlated? Do they convey the same information?
- For variables with missing values: Does it seem like the missingness is linked to the values of any other variables?
We now walk through how we go about answering these questions.
2.5.1 Introduction to ggplot2
In this book, we will use the ggplot2 R package for data visualization. The ggplot2 framework builds plots from composable elements, allowing for extensive customization. The image below shows the seven components used to create a visualization with ggplot2. Of these, the data, mapping,and layers components are required for every plot.

The first step to constructing a data visualization with ggplot2 is to specify the data by passing it into the ggplot() function. This stores the data to be used later by other parts of the plotting system.
ggplot(data=heart)Next, we specify a mapping using aes() within the ggplot() function. Short for aesthetics, this describes how variables in the data are connected to visual properties of the plot. For example, if want Age to map to the x-coordinates and BP to the y-coordinates, we’d state that as follows:
ggplot(heart, mapping = aes(x= Age, y=BP))The last required component for creating a plot are the layers, which take the mapped data and represent it in a way that humans can understand. Every layer consists of a geometry, which determines how the data are displayed (e.g. as points, lines, curves).
Using the code below, we have created our first complete data visualization! The layer geom_point() specifies that each observation should be displayed as a point. Notice that geom_point() is added to the data and mapping components using +. A common mistake when creating visualizations with ggplot2 is to use a pipe (|> or %>%) in place of a +. Just remember, once you start the initial gglot() call, all components become connected with a +.
ggplot(heart, aes(x= Age, y=BP))+
  geom_point()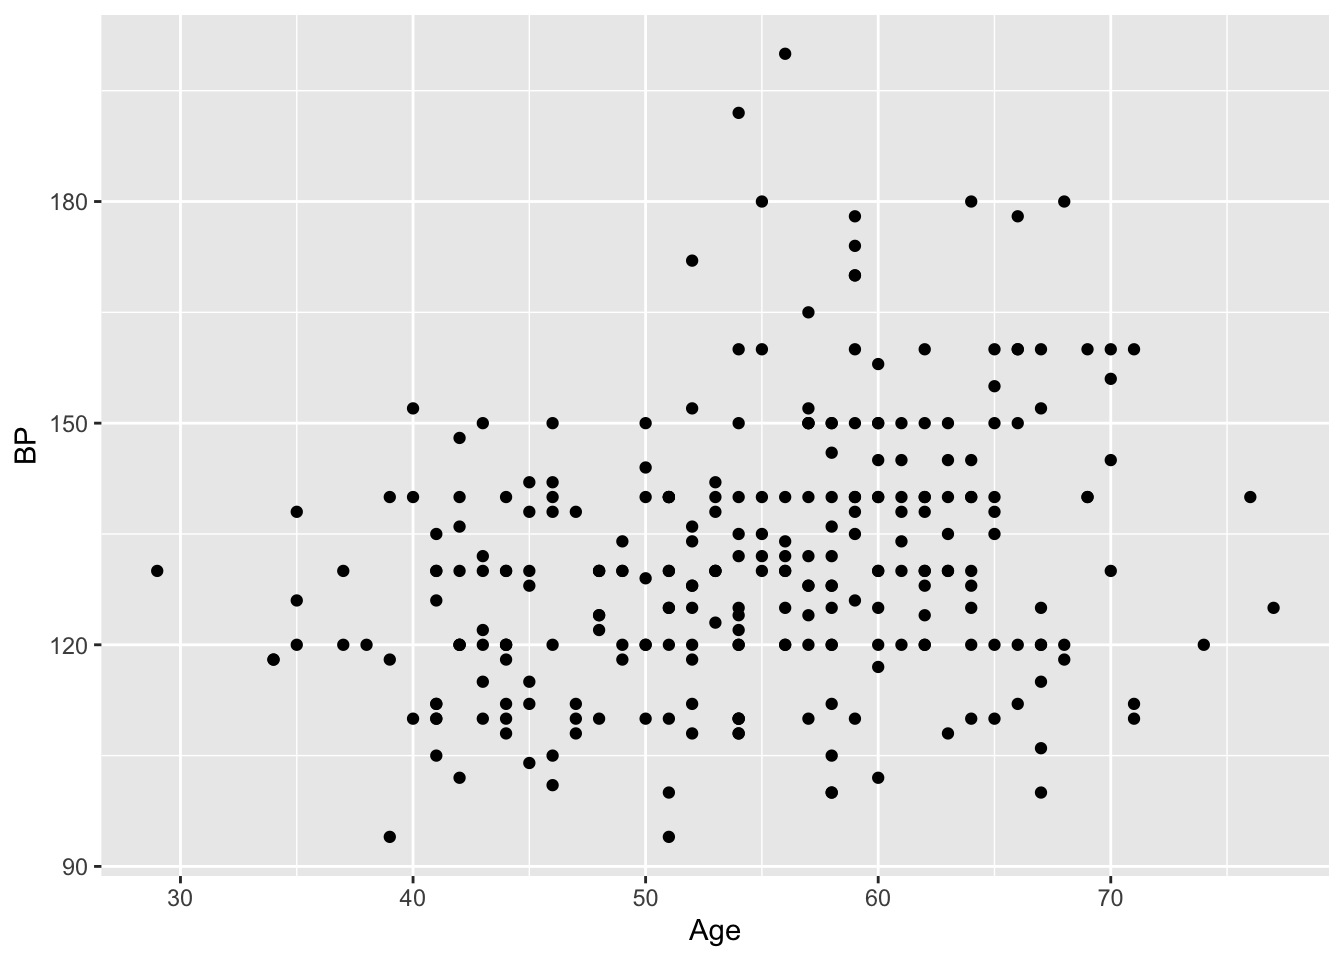
We now introduce what we consider as bonus components. These components have default settings in order to allow the user to build plots more efficiently, which is what makes them not required. However, knowing how to modify them can greatly enhance the clarity of your visualizations.
The first of these components is scales. Scales may be responsible for updating the limits of a plot, setting the breaks, formatting the labels, or applying a transformation. To add a scales component, find a function patterned as scale_{aesthetic}_{type}(), where {aesthetic} is one of the pairings made in the mapping part of a plot. For instance, below we map the Disease variable to the viridis color palette. Additionally, we state that we want more granularity of labels on the y-axis using scale_y_continuous() with n.breaks=6 (notice in the plot above, there were only four).
ggplot(heart, aes(x= Age, y=BP, color = Disease))+
  geom_point()+
  scale_color_viridis_d()+
  scale_y_continuous(n.breaks = 6)
Our next optional component is facets. Facets can be used to split up the plot into smaller panels based on one or more variables. They are especially helpful when trying to visualize trends within multiple subsets at once. For example, in the plot below, facets allow us to compare the relationship between Age and BP for males to females. By coloring by Disease, we can see more males in the dataset have heart disease than females.
ggplot(heart, aes(x= Age, y=BP, color = Disease))+
  geom_point()+
  scale_color_viridis_d()+
  scale_y_continuous(n.breaks = 6)+
  facet_wrap(~Gender)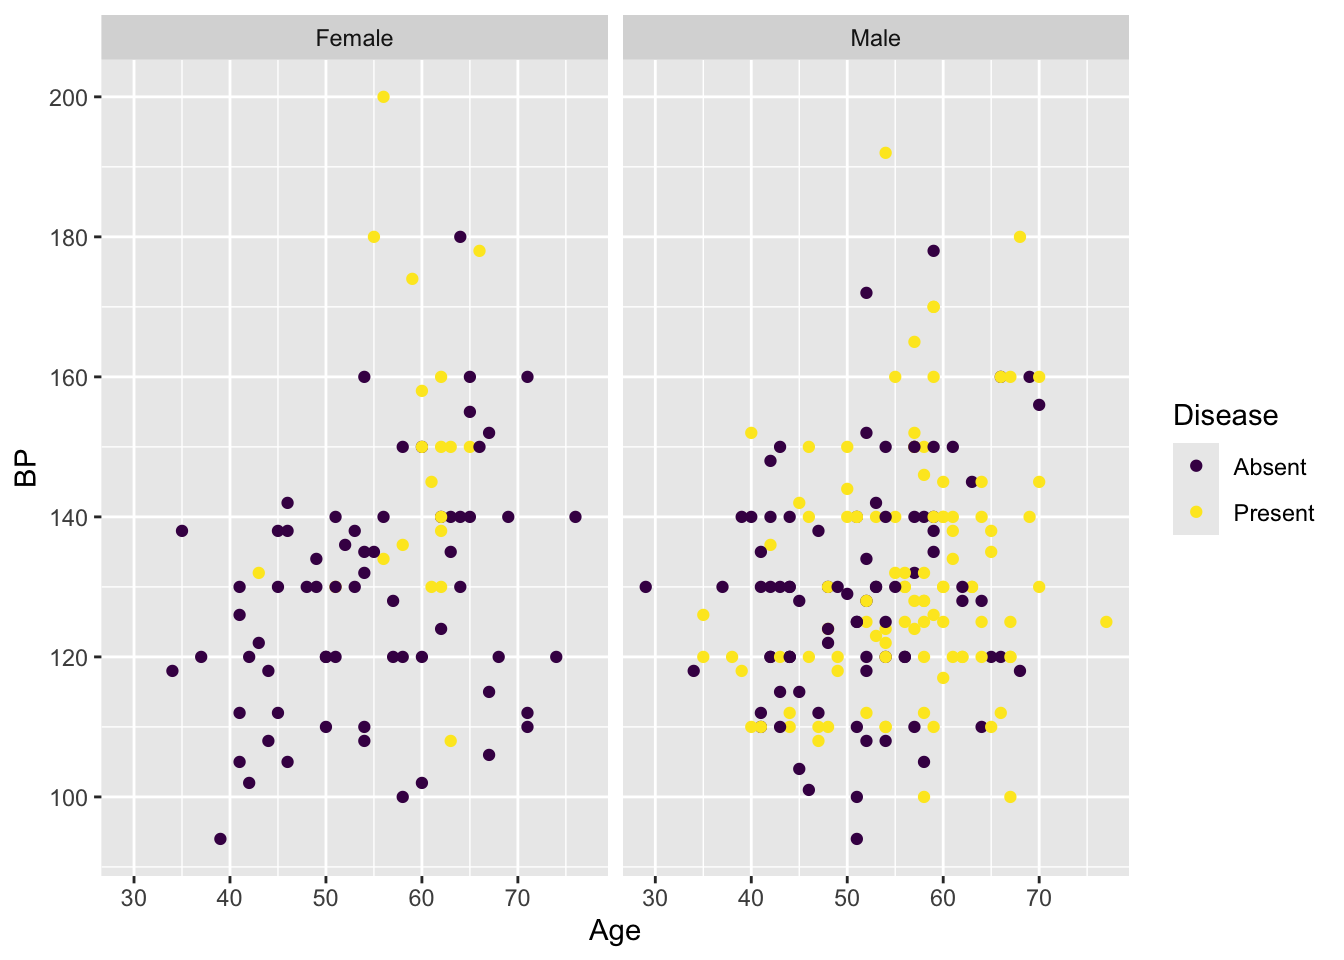
A third optional component is coordinates. The vast majority of the time, Cartesian coordinates are used, but certain data may be well-suited for polar or radial coordiates. Another useful coord_{} function is coord_fixed(). This can be used to display a plot with a fixed aspect ratio so that one unit has the same length in both the x and y directions. note: silly with current example.
ggplot(heart, aes(x= Age, y=BP))+
  geom_point()+
  coord_fixed()
Finally, there is the theme component, where all additional customizations related to the look of the plot are done. The theme can be used for additional customizations including changing the background color, removing the legend, changing the size of the text, and much more. ggplot2 offers a variety of pre-designed themes to choose from (theme_bw(), theme_classic(), and theme_minimal() are some of our personal favorites!), each of which can be further customized with the theme() function.
ggplot(heart, aes(x= Age, y=BP, color = Disease))+
  geom_point()+
  scale_color_viridis_d()+
  theme_bw()+
  theme(legend.position = "bottom")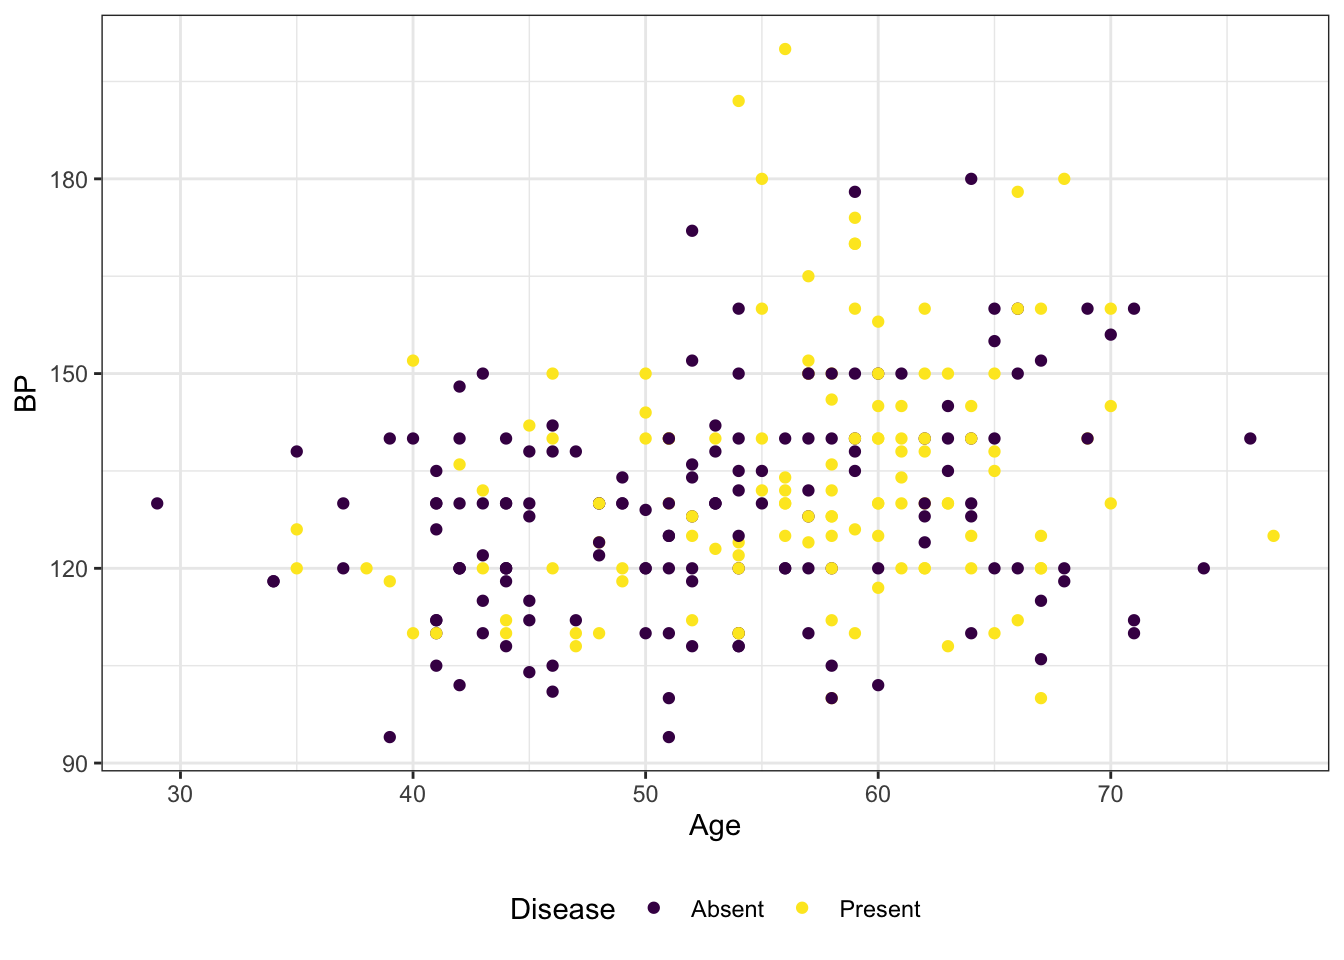
2.5.2 Types of visualizations
TODO: Flow chart/table of when to use different data visualizations. For now, this diagram in by Bin Yu and Rebecca Barter is a great resource.
2.5.3 Example
Let’s now go through an example of the EDA process using Lisa’s Vegetable Garden Data1. We will specifically explore Lisa’s planting and harvesting in 2020. We start by importing the data directly from Github.
planting_2020 <- readr::read_csv('https://raw.githubusercontent.com/rfordatascience/tidytuesday/main/data/2024/2024-05-28/planting_2020.csv')
harvest_2020 <- readr::read_csv('https://raw.githubusercontent.com/rfordatascience/tidytuesday/main/data/2024/2024-05-28/harvest_2020.csv')
2.5.3.1 Understand how the data is structured
Our first step in the EDA process is to understand how the data is structured. Let’s start with the planting_2020 dataset. A nice way to get a quick overview of our data is the glimpse() function.
glimpse(planting_2020)Rows: 93
Columns: 7
$ plot <chr> "A", "B", "H", "P", "C", "C", "D", "D", "I", "P",…
$ vegetable <chr> "peas", "peas", "onions", "onions", "lettuce", "r…
$ variety <chr> "Super Sugar Snap", "Magnolia Blossom", "Long Kee…
$ number_seeds_planted <dbl> 22, 24, 40, 25, 60, 20, 5, 8, 10, 30, 30, 50, 50,…
$ date <date> 2020-04-19, 2020-04-19, 2020-04-26, 2020-04-26, …
$ number_seeds_exact <lgl> TRUE, TRUE, FALSE, FALSE, FALSE, FALSE, FALSE, FA…
$ notes <chr> NA, NA, NA, NA, NA, NA, NA, NA, NA, NA, NA, NA, N…We can see that planting_2020 includes seven variables and 93 observations. We appear to have four character variables (plot, vegetable, variety, and notes), one numeric variable (number_seeds_planted), one date variable (date), and one logical variable (number_seeds_exact). Below, we change plot, vegetable, and variety to factors. Typically, characters are for general-purpose text strings, while factors are for categorical data with a fixed set of predefined levels. In this case, plot, vegetable, and variety can only take a number of values—Lisa only has so many plots, and there are only so many types of vegetables and vegetable varieties. On the other hand, notes, which we notice is mostly missing, is a place for Lisa to write various notes if necessary. These notes can be anything, thus leaving it as a character is appropriate.
planting_2020 <- planting_2020 %>%
  mutate(across(c(plot, vegetable, variety), as.factor))
Let’s also check out the harvest_2020 data.
glimpse(harvest_2020)Rows: 781
Columns: 5
$ vegetable <chr> "lettuce", "radish", "lettuce", "lettuce", "radish", "lettuc…
$ variety <chr> "reseed", "Garden Party Mix", "reseed", "reseed", "Garden Pa…
$ date <date> 2020-06-06, 2020-06-06, 2020-06-08, 2020-06-09, 2020-06-11,…
$ weight <dbl> 20, 36, 15, 10, 67, 12, 9, 8, 53, 19, 14, 10, 48, 58, 8, 121…
$ units <chr> "grams", "grams", "grams", "grams", "grams", "grams", "grams…We have five variables and 781 observations, where each observation represents a harvest of a particular vegetable variety. Just like in planting_2020, we can convert vegetable and variety factors. units can be additionally treated as a factor—we’ll want to check and make sure all rows take the same units so that we can compare the weight across different observations.
harvest_2020 <- harvest_2020 %>%
  mutate(across(c(vegetable, variety, units), as.factor))
2.5.3.2 Understand relevant variables individually
Now that we understand what information is included in planting_2020 and harvest_2020, let’s create some univariate summaries and visualizations.
First, let’s start with checking for missingness in each variable. An easy way to do this is using the vis_miss() function from naniar package.
library(naniar)
vis_miss(planting_2020)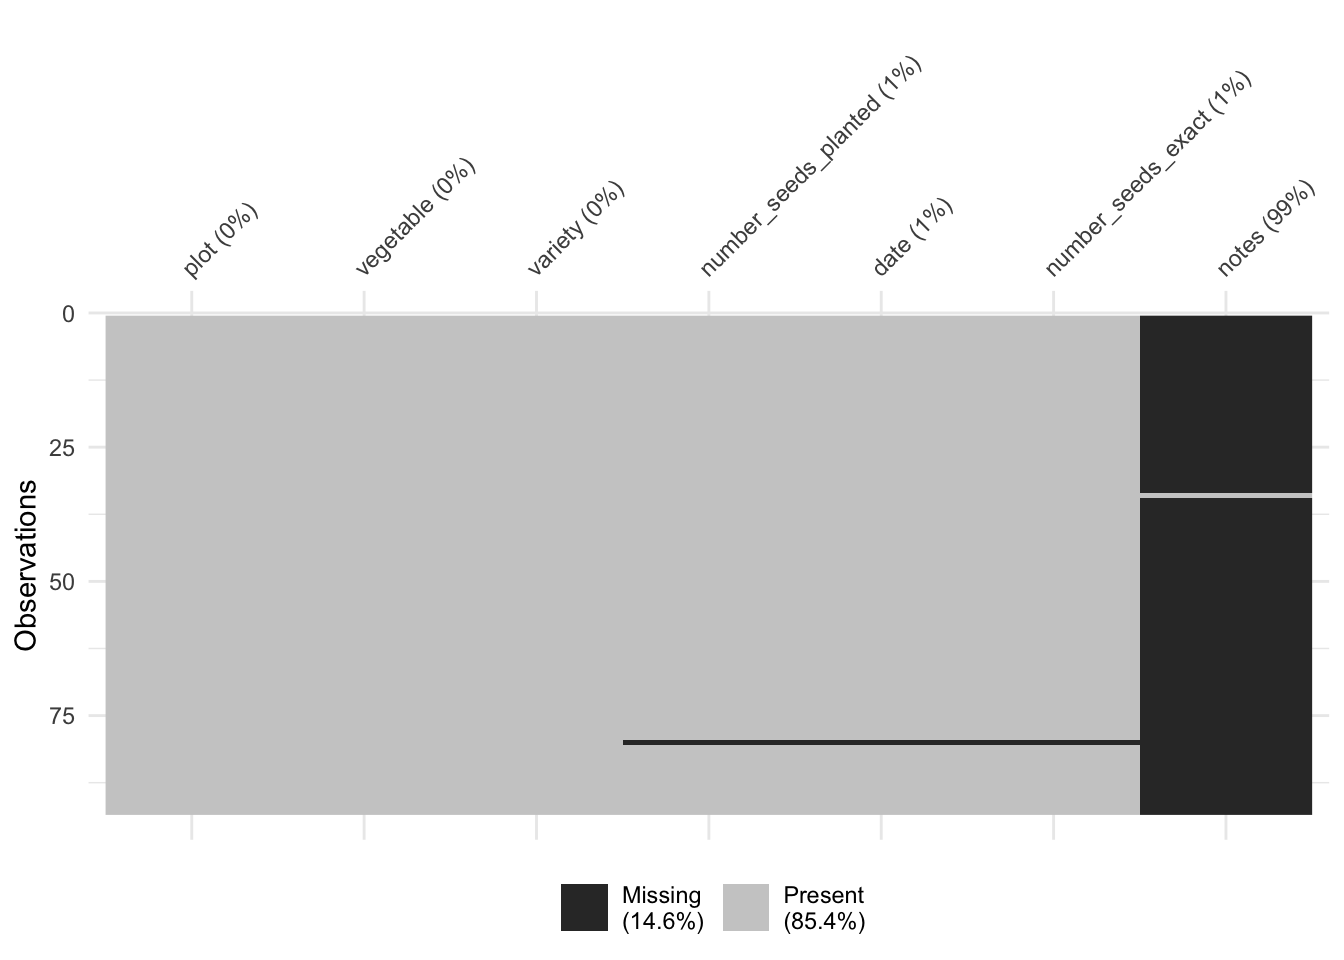
vis_miss(harvest_2020)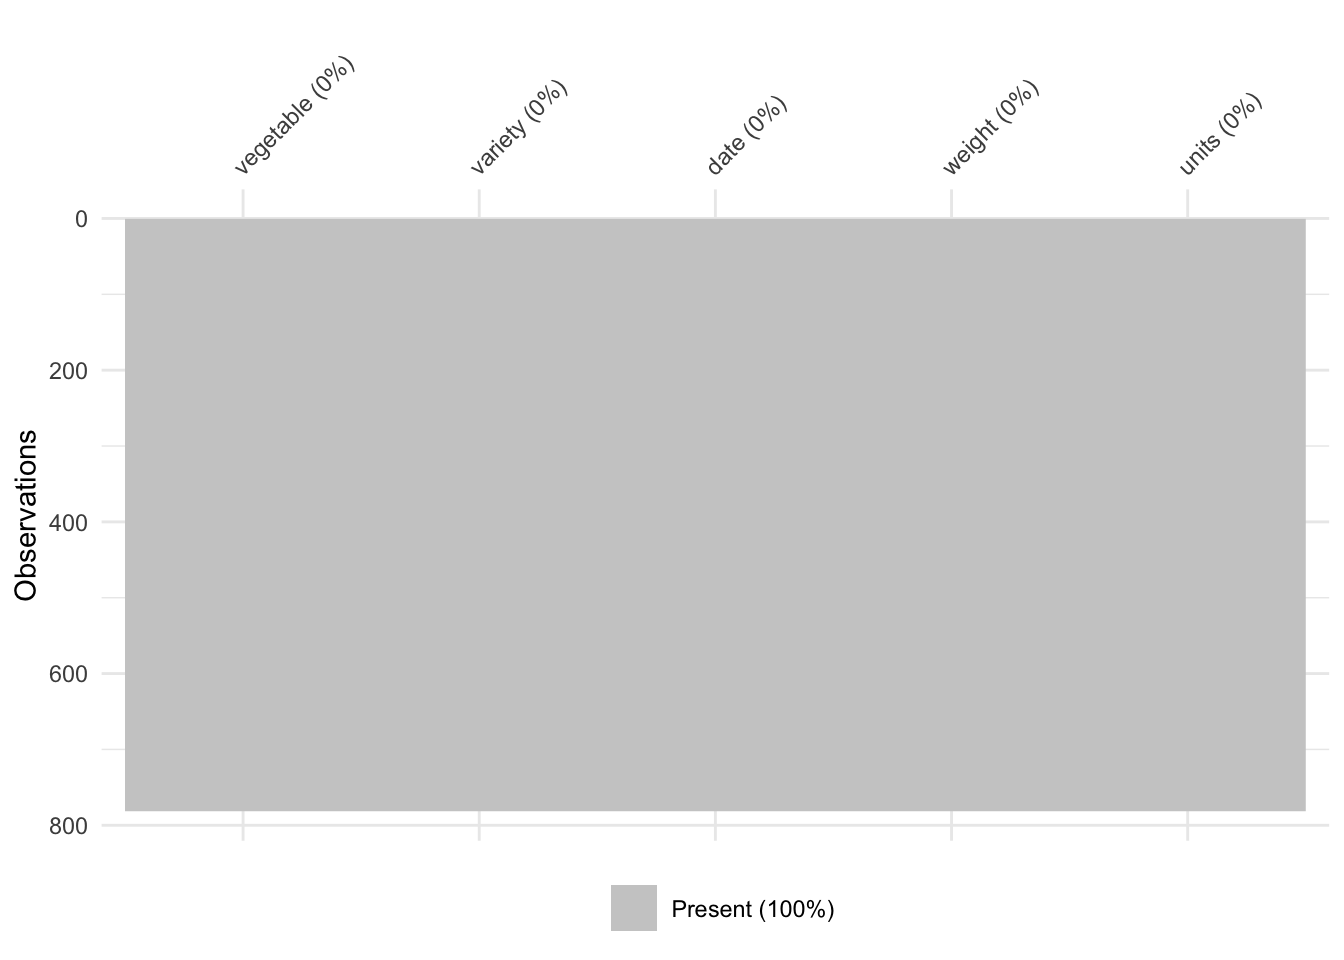
Above, we see there is no missingness in the harvest_2020 dataset. On the other hand, however, the note variable in planting_2020 is almost entirely missing. This makes sense as column is an optional place for Lisa to leave extra comments. We do, however, have one observation where Lisa did not record information about the number of seeds she planted or the date. Investigating further, we see this is for perennial strawberries.
planting_2020 %>% filter(is.na(number_seeds_planted))# A tibble: 1 × 7
plot vegetable variety number_seeds_planted date number_seeds_exact
<fct> <fct> <fct> <dbl> <date> <lgl>
1 F strawberries perenni… NA NA NA
# ℹ 1 more variable: notes <chr>Having looked at missigness, let’s start with some univariate summaries and visualizations of categorical variables. We can use count() with nrow() to check how many values each categorical variable takes. Using count() alone will tell us the number of observations of each level of our categorical factor variable.
planting_2020 %>% count(vegetable)# A tibble: 31 × 2
vegetable n
<fct> <int>
1 basil 1
2 beans 5
3 beets 2
4 broccoli 3
5 brussels sprouts 1
6 carrots 6
7 cilantro 2
8 corn 2
9 cucumbers 1
10 dill 1
# ℹ 21 more rowsAdding on nrow() tells us simply the number of levels. Below, we can see Lisa planted 31 different vegetables (wow!) with 65 unique varietes in 23 different plots.
planting_2020 %>% count(vegetable) %>% nrow()[1] 31planting_2020 %>% count(variety) %>% nrow()[1] 65planting_2020 %>% count(plot) %>% nrow()[1] 23We can use a bar chart to see how many times Lisa recorded a planting of each vegetable. Let’s arrange from most to least plotted vegetables, make the bars horizontal, and change the theme. We can see that Lisa recorded many plantings of tomatoes and squash—we’ll have to check later on if these were the vegetables she harvested the most!
planting_2020 %>%
  count(vegetable) %>%
  ggplot(aes(x= n , y = fct_reorder(vegetable, n)))+
  geom_col() +
  theme_bw()+
  labs(x= "Number of plantings", y= "")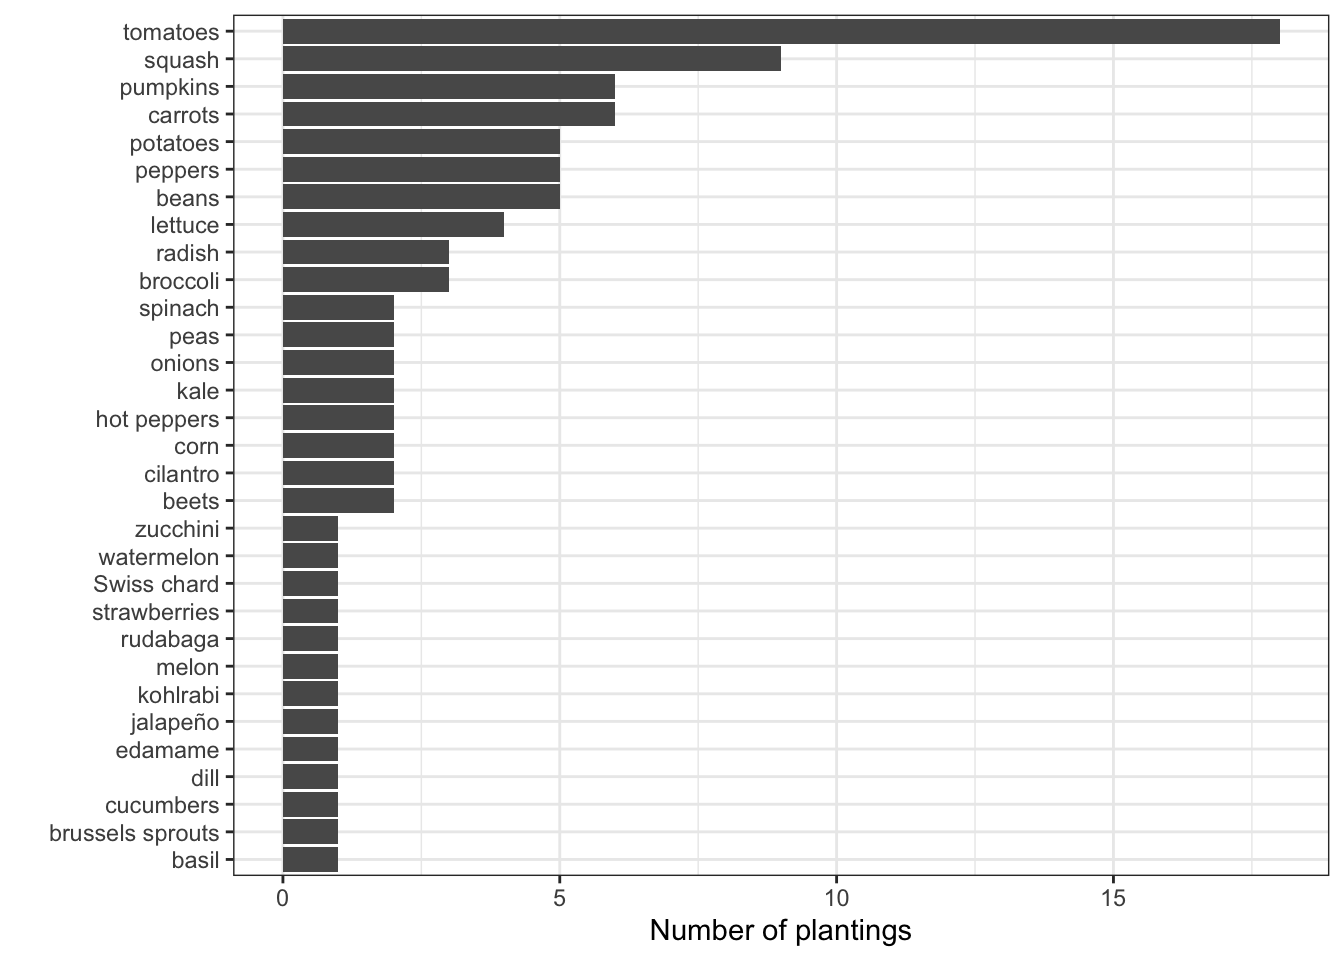
Now, let’s check out how many seeds Lisa was using in each recorded planting. Because seeds is a continuous variable, a histogram is appropriate here. Note the warning message: Warning: Removed 1 row containing non-finite outside the scale range (stat_bin()). This row represents the missing value that we previously identified.
planting_2020 %>%
  ggplot(aes(x=number_seeds_planted))+
  geom_histogram(binwidth = 5)+
  theme_bw()+
  labs(x="Number of seeds planted")
Warning: Removed 1 row containing non-finite outside the scale range
(`stat_bin()`).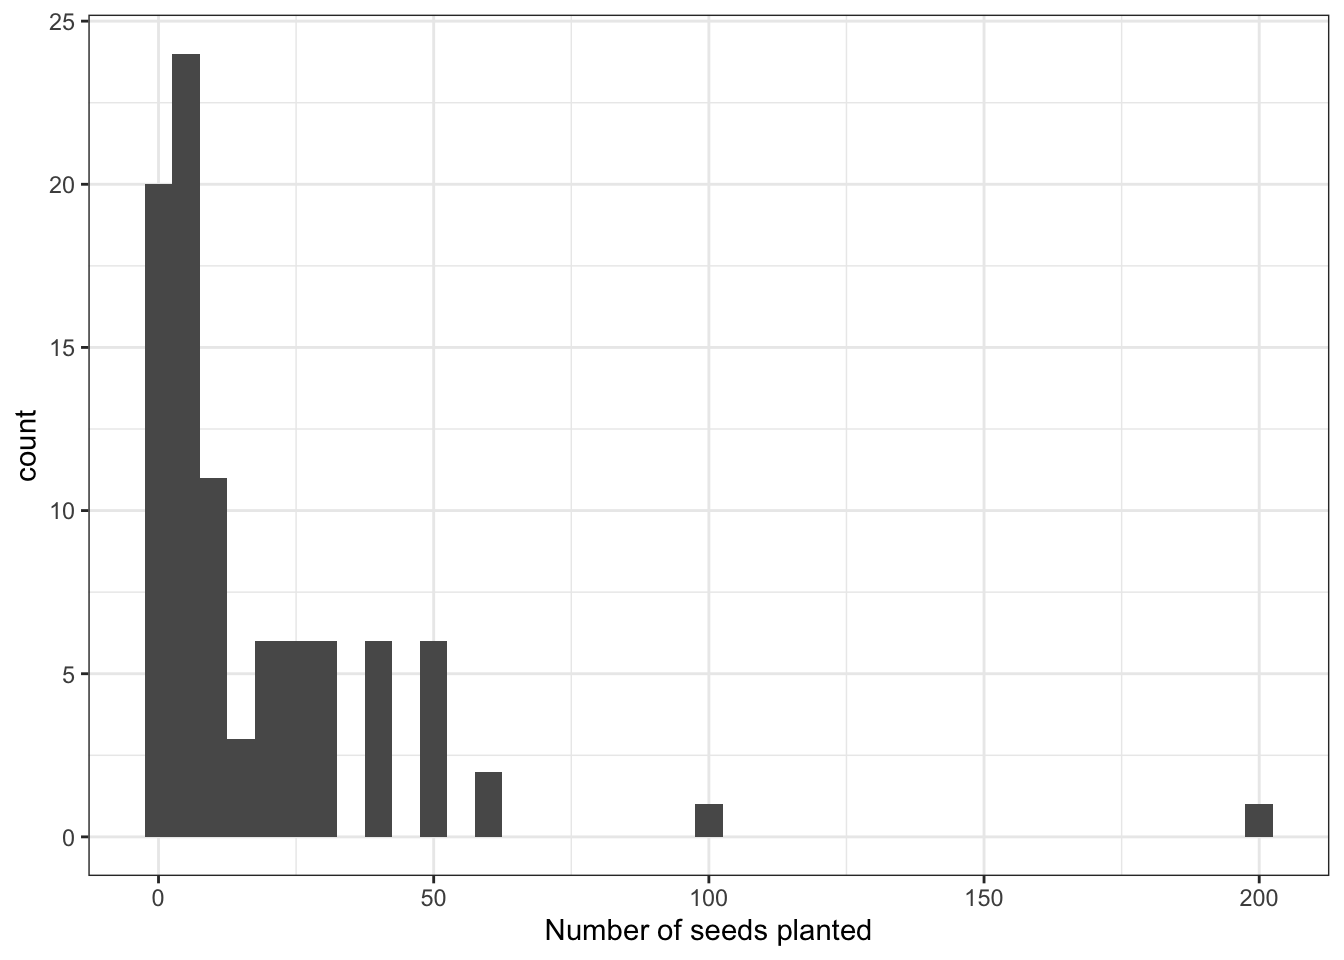
Above, we set the binwidth to five, meaning each vertical bar represents a five wide range of seeds planted (e.g. 1-5 seeds, 6-10 seeds, etc). It appears that most often Lisa is planting between 1-15 seeds, with the distribution being right skewed. For a couple of plantings, Lisa planted roughly 100 and 200 seeds, which are visual outliers. Checking these observations out, we see they are lettuce and spinach plantings, and number_seeds_exact tells us that the number of seeds planted in both cases was an estimate.
planting_2020 %>%
  filter(number_seeds_planted > 90)
# A tibble: 2 × 7
plot vegetable variety number_seeds_planted date number_seeds_exact
<fct> <fct> <fct> <dbl> <date> <lgl>
1 E spinach Catalina 100 2020-06-20 FALSE
2 G lettuce Lettuce Mi… 200 2020-06-20 FALSE
# ℹ 1 more variable: notes <chr>Let’s also do some univariete EDA of harvest_2020. First, let’s see how many harvests Lisa made each month in 2020. To do this, we will use the month() function from the lubridate R package. Below, we see that harvest season is from June through October, with Lisa making almost 300 harvests in August.
harvest_2020 %>%
  mutate(harvest_month = month(date, label =T)) %>%
  group_by(harvest_month) %>%
  count() %>%
  ggplot(aes(x=harvest_month, y=n))+
  geom_col()+
  labs(x="Harvest month", y= "Number of harvests")+
  theme_bw()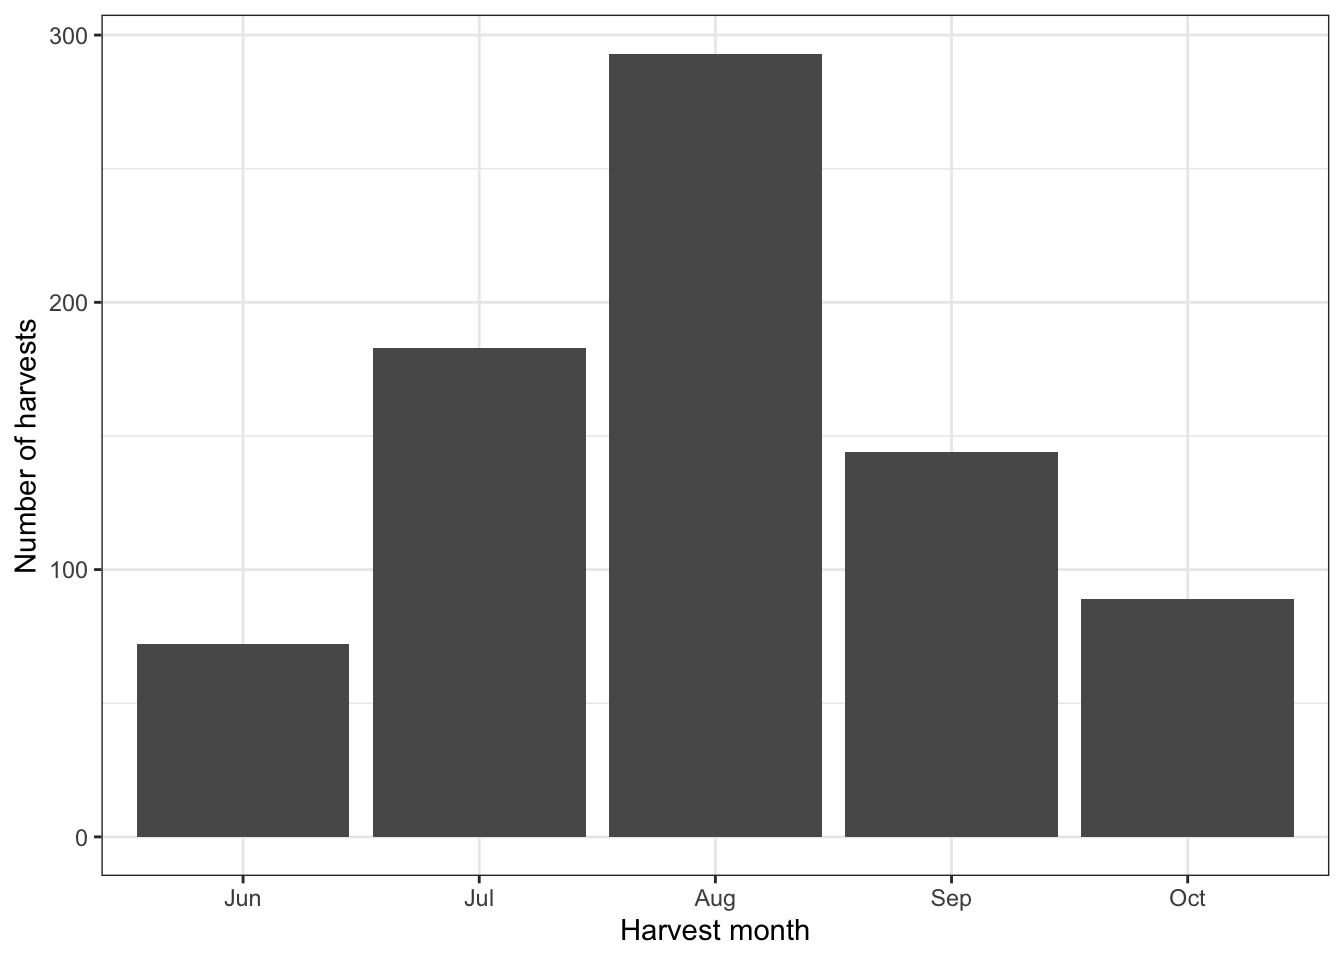
Finally, let’s check out the distribution of the weight of these harvests. We first confirm that all harvests are weighed in grams.
unique(harvest_2020$units)[1] grams
Levels: gramsUsing a density plot, below we find that the distribution of harvest weights is heavily right skewed. While most vegetable harvests are under 1000 g, it appears Lisa had at least one harvest over 7000 g. A good next step will be to understand what vegetables have particularly heavy or light harvests. This brings us to the final step of our EDA process, exploring relationships between variables.
harvest_2020 %>%
  ggplot(aes(x=weight))+
  geom_density()+
  theme_bw()+
  labs(x = "Weight (g)")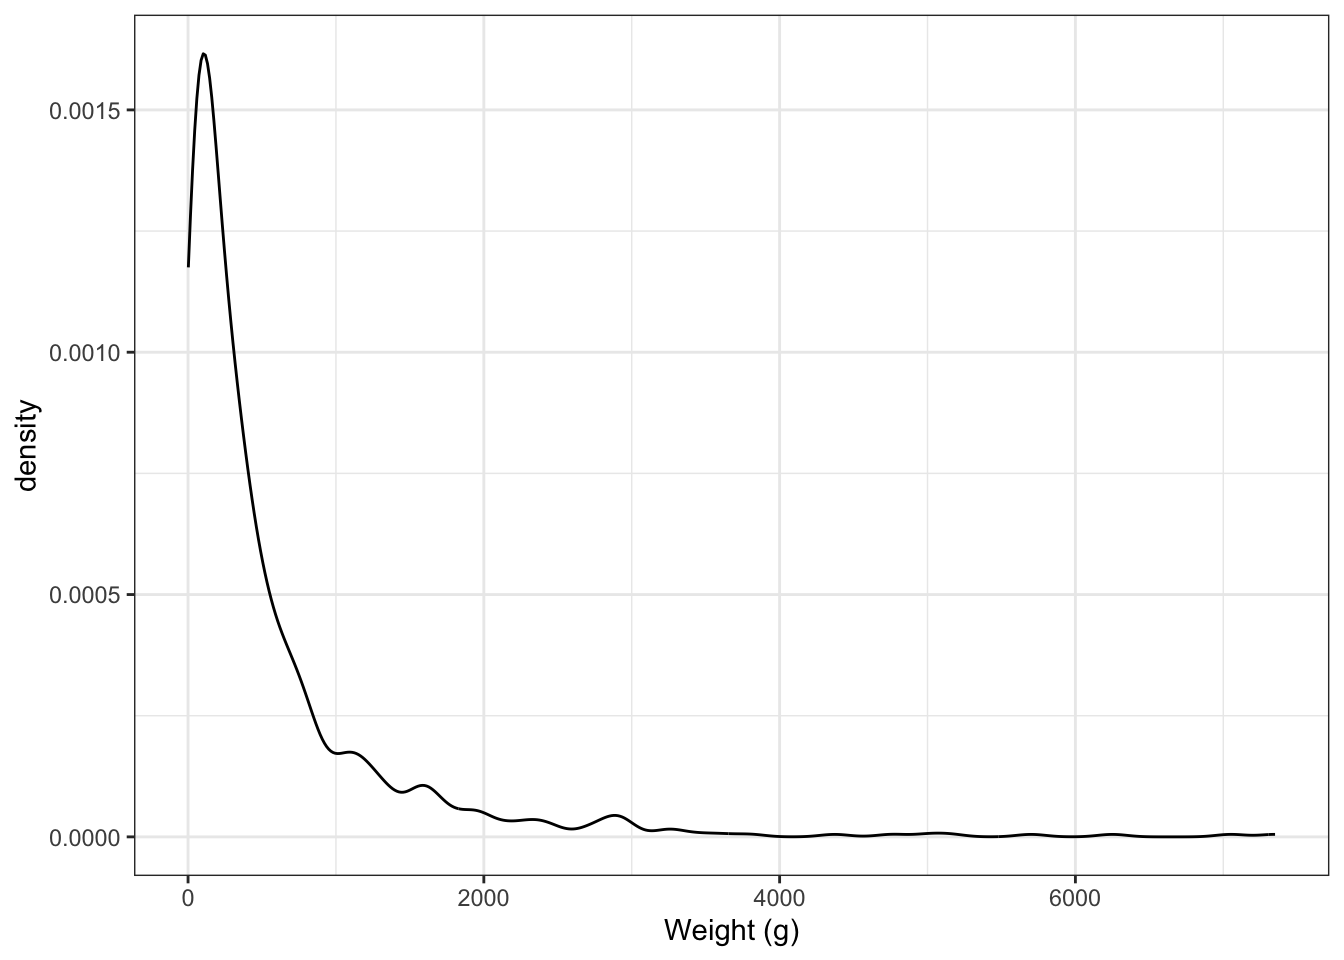
2.5.3.3 Explore relationships between variables
Let’s continue with the harvest_2020 dataset to start, specifically with our question about understanding harvest weight by vegetable. In particular, let’s first identify the vegetables with the smallest and largest average harvest weight.
avg_harvest_weight_by_veg <- harvest_2020 %>%
  group_by(vegetable) %>%
  summarize(n_harvests = n(), avg_harvest_weight = mean(weight)) %>%
  arrange(avg_harvest_weight)

avg_harvest_weight_by_veg %>%
  slice_head(n = 5)
# A tibble: 5 × 3
vegetable n_harvests avg_harvest_weight
<fct> <int> <dbl>
1 chives 1 8
2 cilantro 3 17.3
3 asparagus 1 20
4 basil 15 32.7
5 spinach 22 42.0avg_harvest_weight_by_veg %>%
slice_tail(n = 5)# A tibble: 5 × 3
vegetable n_harvests avg_harvest_weight
<fct> <int> <dbl>
1 corn 8 738.
2 rutabaga 17 794.
3 zucchini 37 1222.
4 squash 34 1321.
5 pumpkins 25 2806.It makes sense that leafy vegetables (e.g. cilantro, basil, spinach) have low average harvest weights while bigger vegetables (e.g. squash, pumpkins) have a heavy average harvest weight.
It may also be interesting to explore there relationship between number of seeds planted and harvest weight. To do so, let’s create two data frames: vegetable_seeds, representing the number of seeds Lisa planted for each vegetable variety, and harvest_weights, representing the total weight of each vegetable variety that Lisa harvested. Along the way, we correct a couple spelling mistakes in order to obtain properly joined rows2. We also replace missing values with zero. This represents situations where Lisa harvested without planting any seeds (e.g. perennial plants) or planted seeds but the plant did not produce any crops.
vegetable_seeds <- planting_2020 |>
  group_by(vegetable, variety) |>
  summarize(n_seeds = sum(number_seeds_planted))


harvest_weights <- harvest_2020 |>
  group_by(vegetable, variety) |>
  summarize(harvest_weight_lbs = sum(weight)/454) |>
  mutate(vegetable = case_when(vegetable == "rudabaga" ~ "rutabaga",
                               TRUE ~ vegetable),
         variety = case_when(variety == "perrenial" ~ "perennial",
                             TRUE ~ variety))

plant_harvest <- vegetable_seeds |>
  full_join(harvest_weights, by = c("vegetable", "variety")) |>
  mutate(harvest_weight_lbs = replace_na(harvest_weight_lbs, 0),
         n_seeds = replace_na(n_seeds, 0))
We can now create a scatterplot with number of seeds planted on the x-axis and harvest weight on the y-axis. The scatterplot displays a weak, negative relationship between total seeds planted and harvest weight. Interestingly, for several plants (Romanesco zucchini, saved pumpkins, Amish Paste tomatoes, Volunteers tomatoes), Lisa planted under only a few seeds but harvested over fifty pounds of each vegetable variety. On the other hand, for a few different lettuce and carrot varieties, Lisa planted (or estimated that she planted) over one hundred seeds, but harvested under ten pounds of each vegetable variety.
plant_harvest |>
  ggplot(aes(x=n_seeds, y=harvest_weight_lbs))+
  geom_point(color = "darkgreen", alpha=0.5)+
  theme_bw()+
  labs(x="Total seeds planted", y= "Harvest weight (lbs)")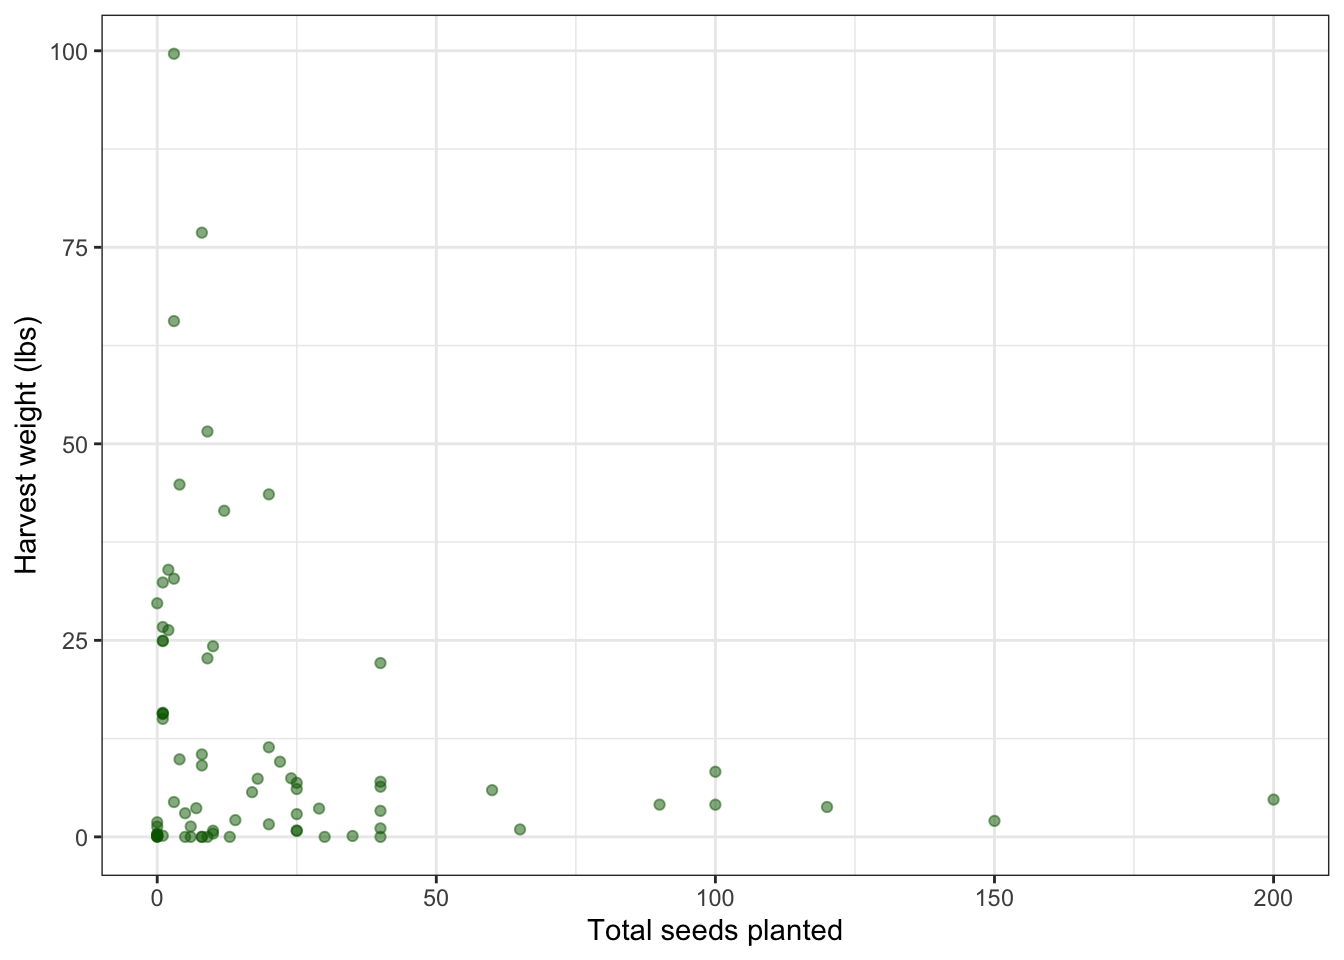
There are so many more questions to explore with this dataset, and we encourage you to continue to investigate what interests you! The plots we have created so far are a good start to get an overview of the datasets, but it is important to tailor further EDA to your specific research question.
2.6 Anomaly Detection
An anomaly, or outlier, is a data point located outside the general scope of the other observations. Most generally, beyond the general scope of other observations means that the data point stands apart from the rest by the naked eye. Such points can be discovered through the exploratory data analysis process. For instance, we don’t need a mathematical formula to tell us that the single point to the lower right in the figure below is an outlier. It clearly doesn’t follow the positive, linear trend displayed by the other observations.
TODO: image fuzzy, generate a new one and replace

EDA should always be the first path for identifying outliers. As we walk through the steps described in Section XYZ to understand our data and explore our research question, we should take note of data points that are beyond the general scope of the other observations. Note, however, that outlier data points may not always be easy to pick out. Suppose we only visualized the data in Figure XYZ in one dimension. In that case, we would not see the anomalous point at all! By the same token, we who exist and see in three dimensions might not see anomalies present in the higher-dimensional data that we often build models with. Thus, we should always visualize the data before modeling, but visualization on its own will not guarantee that we will catch all anomalous data points.
In addition to visual methods, quantitative rules can be used to identify outliers. A common approach labels observations as outliers if they fall more than 1.5 times the interquartile range (IQR) below the first quartile or above the third quartile. This is the criterion used to draw the whiskers and identify outliers in a boxplot. The problem with this approach is that it is sensitive to sample size. By properties of the normal distribution, for a perfectly normally distributed variable, about 0.7% of observations are expected to fall outside the boxplot whisker. For 100 observations, we’d expect less than one outlier. But for 10,000 observations, we will observe approximately 70 observations that are flagged to be outliers, even though they are simply observations from the tails of the distribution and are not truly anomalous. To use this method for very large sample sizes, we may therefore need to increase the whisker lengths.
TODO: may change/reference image 
Idenitying outliers using the 1.5 IQR rule is also limited in that it is inherently univariate. By only assessing one variable at a time, it can miss outliers visible in multipe dimensions, such as the observation in the bottom right corner in Figure XYZ. As a result, quantitative methods for identifying outliers in high-dimensional data often rely on pairwise distance measures between observations. Suppose observations \(i\) and \(j\) have quantitative feature vectors \(\mathbf{x}_i = \{x_{i1}, \dots, x_{ip}\}\) and \(\mathbf{x}_j = \{x_{j1}, \dots, x_{jp}\}\), respectively. The Euclidean distance between the two observations is \[ D_{ij} = \sqrt{(x_{i,1}-x_{j,1})^2 + \cdots + (x_{i,p}-x_{j,p})^2} \,. \] For each observation, we can determine the euclidean distance to its nearest neighbor and construct a histogram of these minimum distances. Most observations will have relatively small minimum distances, while an anomalous observation may stand out as having an unusually large minimum distance, indicating that it is isolated from the rest of the data.
TODO: show code calculating pairwise distances and mention (Note that, e.g., there are efficient methods in R and Python for generating the full ensemble of pairwise distances and storing them in an \(n \times n\) symmetric matrix (which zeros along the diagonal), but beware: the memory required to store a matrix is such that these methods are only really applicable if the number of rows is \(\lesssim\) 20,000.)
One limitation of Euclidean distance is that it depends on the scale of the variables. Consequently, variables with larger variances or numerical ranges contribute disproportionately to the computed distances. As a simple example, changing the units of a variable miles from kilometers to millimeters will greatly increase its influence on the Euclidean distance, even though the information this variable contains is unchanged. Consequently, an often used alternative approach to computing the Euclidean distance is to compute the Mahalanobis distance \[
D_i = \sqrt{(\mathbf{x}_i-\bar{\mathbf{x}})^T \Sigma^{-1} (\mathbf{x}_i-\bar{\mathbf{x}})} \,,
\]
where \(\mathbf{x}_i\) represents a single row of the data (all observed values for observation \(i\)) and \(\bar{\mathbf{x}}\) represents the average values for each variable. \(\Sigma^{-1}\) is the inverse of the covariance matrix, which describes the spread of the data. Its diagonal entries contain the variances of each variable, while its off-diagonal entries contain the covariances between pairs of variables, indicating how strongly they vary together. By incorporating the covariance matrix, the Mahalanobis distance automatically adjusts for differences in scale and for correlations among the variables, making it a more meaningful measure of distance in multivariate data. \(D_i\), the Mahalanobis distance, is not a pairwise distance but rather the distance from the global average point in \(p\)-dimensional space of the data. Creating a histogram of each observation’s Mahalanobis distance can help identify points that lie anomalously far from the global average point.
2.6.1 Removing outliers
Now that we have discussed how to identity outliers, we should outline how to handle them. In short, dealing with outliers requires careful judgment. Just as there are not hard and fast rules for what makes a data point an outlier, there is no singular rule for whether or not to remove an outlier from the analysis. However, there are a few guiding questions we can ourselves.
- Is outlier is due to some kind of measurement or recording error?
- If so, and we can confidently correct the error, we can keep it in the analysis.
- If not, we must make the difficult decision of whether to keep the outlier and acknowledge that it may significantly influence our estimates—or to remove it and risk throwing away good information.
There are two pieces of information that can help us make this difficult decision. The first is leverage.
As a final note, regardless of what quantitative approach we take, we need to explicitly record what data points we deem to be anomalous (and remove from the dataset)! We always record our choices, to ensure our analyses are reproducible.
2.7 Optional: Data Reduction via Principal Components Analysis
- Let’s build up intuition for PCA by starting off with a picture:

At left, we visualize the contents of a data frame with six rows (six data points) and two columns, \(x_1\) and \(x_2\)
What does the PCA algorithm do? It utilizes algorithms of linear algebra to move the coordinate system origin to the centroid of the point “cloud,” then rotates the axes such that “PC 1” lays along the direction of greatest variation (i.e., along the points), and “PC 2” lays orthogonal to to “PC 1”
In the end, PCA is the linear transformation of a coordinate system…
…but, there is actually more to PCA then just the transformation.
At right, we move into “PC space,” where PC1 has become the \(x\) axis, etc.
Note how the data all lie along the PC1 axis
in PC space, we can see that the true space of the data is one-dimensional: a second dimension adds no statistical information at all
we can visualize and interpret the data using, e.g., a histogram of PC1 values and ignore PC2 entirely
So in the end, PCA is also a dimension-reduction tool
2.7.1 Why Use PCA?
There are two principal (pun not intended) reasons to use PCA:
it can assist data visualization: if the predictor data lay within a subspace of the native space, we can try to visualize the data in that space
it can help statistical inference: PCA “decorrelates” the data \(-\) there is no linear association between the data along PC1 and PC2, etc. \(-\) so multicollinearity is mitigated!
NOTE: PCA is not appropriate for use with categorical data!
2.7.2 It’s a Linear Algorithm
- The main limitation of PCA is that it is a linear algorithm: it projects data to hyperplanes

These data lay on a curving two-dimensional strip embedded in a three-dimensional space
projecting these data to a two-dimensional plane or a one-dimensional line would effectively randomize the statistical information they contain
for visualization and/or learning, we could explore the use of nonlinear techniques like diffusion map or local linear embedding, or self-organizing maps or tSNE, etc.
2.7.3 It’s Not Factor Analysis
PCA is one of a family of related algorithms commonly dubbed factor analyses, and, for instance, some use the phrases “PCA” and “factor analysis” interchangeably
The PCA algorithm as described here is a deterministic algorithm: it just ingests the data values as they are and produces a result, full stop
Exploratory factor analysis is a variant of PCA which does attempt to take the random variability of the data into account
- it maps the \(p\) observed variables to \(k < p\) factors; “exploratory” means we do not know a priori how that mapping may occur
Confirmatory factor analysis basically adds on a hypothesis-testing layer to EFA for confirming that links actually exist between the \(k\) factors uncovered by EFA and the \(p\) original variables
2.7.4 Algorithm


The score, or the coordinate of the \(i^{\rm th}\) observation along PC \(j\) is \[Z_{ij} = \sum_{k=1}^p X_{ik} \phi_{kj}\]
\(k\) represents the \(k^{\rm th}\) variable or feature (i.e., the \(k^{\rm th}\) column of your [predictor] data frame)
\(\phi\) is the rotation (or loading) matrix, which is normalized such that \(\sum_{k=1}^p \phi_{kj}^2 = 1\)
Note that since we are “mixing axes” when doing PCA, it is generally best to standardize (or scale) the data frame before applying the algorithm
2.7.5 Choosing the Number of Dimensions to Retain
Ideally, we choose \(M < p\) such that \[x_{ij} = \sum_{m=1}^p z_{im}\phi_{jm} \approx \sum_{m=1}^M z_{im}\phi_{jm}\]
- in other words, we don’t lose much ability to reconstruct the input data \(X\) by dropping the last \(p-M\) principal components, which we assume represent random variation in the data (i.e., noise)
One convention is to sum up the amount of variance explained in the first \(M\) PCs, and adopt the smallest value of \(M\) such that 90% or 95% or 99%, etc., of the overall variance is “explained”
Another convention is to look for an “elbow” in the left plot below (the “scree plot”)

2.7.6 Example
- Let’s suppose we have a catalog of galaxies that contains measures of brightness in different wavelength bands, from
u(for ultraviolet) tozandyin the near-infrared
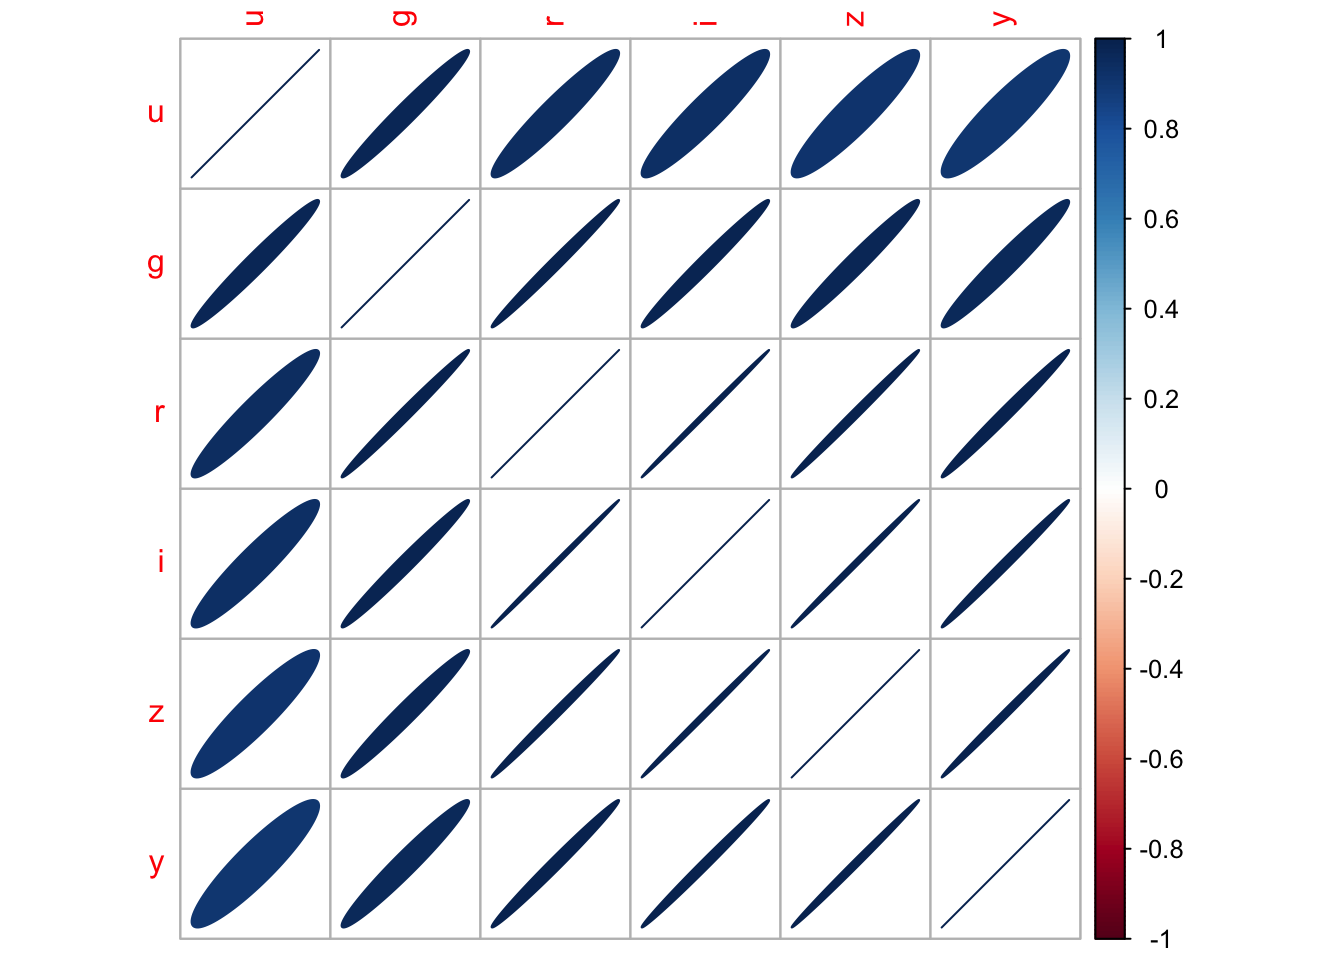
- The six brightness metrics are obviously highly correlated!
pca.out <- prcomp(df[,-7],scale=TRUE) # do not include response variable!
v       <- pca.out$sdev^2
round(cumsum(v/sum(v)),3)
[1] 0.977 0.998 0.999 1.000 1.000 1.000The first principal component explains 97.7% of the variance in the dataset: the data can safely be transformed from a six-dimensional space to a one-dimensional one with minimal loss of statistical information
Let’s print the column(s) for the PCs that we retain:
round(pca.out$rotation[,1],3) u g r i z y
0.396 0.411 0.413 0.412 0.410 0.408 Here, we see that all the original variables contribute almost equally to the first PC (sign doesn’t matter)
- we conclude that the predictor variables (for all intents and purposes) lie along a one-dimensional line in the native six-dimensional space, and that the orientation of the line is such that it spans all six of the original predictor variable axes
What information is in the second PC?
round(pca.out$rotation[,1:2],3) PC1 PC2
u 0.396 0.793
g 0.411 0.247
r 0.413 -0.089
i 0.412 -0.205
z 0.410 -0.320
y 0.408 -0.398- The second PC primarily maps to u-band magnitude…basically, the PC2 vector, orthogonal to the PC1 vector, points largely along the u-band axis, meaning there is some data variability along that axis that PC1 does not “pick up”
2.7.7 PC Regression
TBD: move to extensions to linear regression chapter
Let’s demonstrate how we would learn a principal components regression model using the distance of a galaxy from the Sun as a response variable
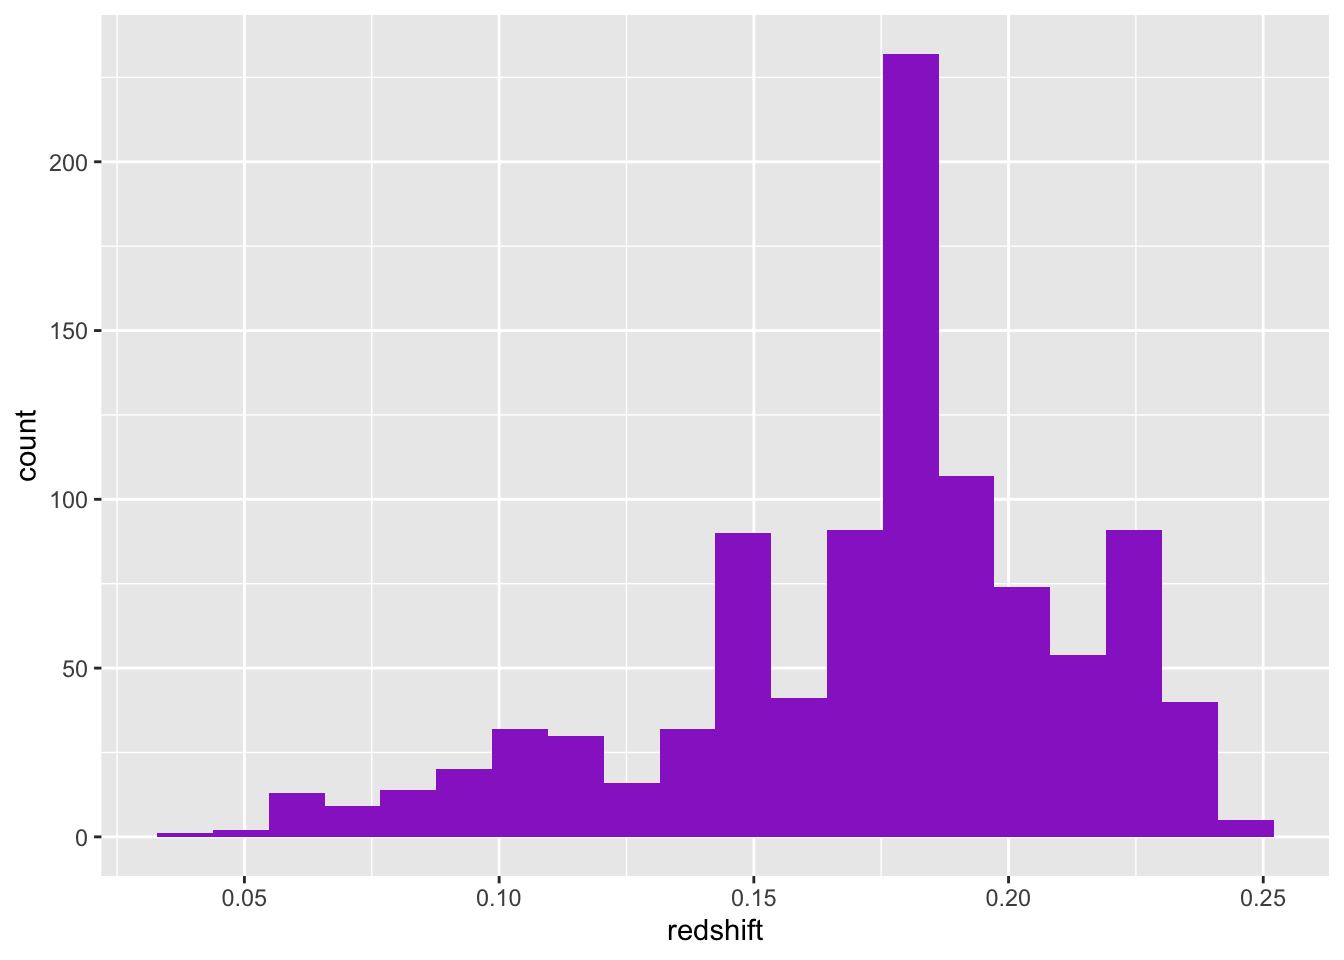
Reminder: why are we doing this?
to mitigate multicollinearity
so we can “trust” the standard error estimates output in the summary
Let’s split the data:
set.seed(101)
s <- sample(nrow(df),round(0.7*nrow(df)))- The test-set mean-squared error for a linear-regression model learned in the data’s native space:
lm.out  <- lm(redshift~.,data=df,subset=s)
lm.pred <- predict(lm.out,newdata=df[-s,])
mean((lm.pred-df$redshift[-s])^2)
[1] 0.0008416416- The test-set mean-squared error for a PC regression model learned using all PCs:
df.pc <- data.frame(pca.out$x,df$redshift)
names(df.pc) <- c("PC1","PC2","PC3","PC4","PC5","PC6","y")
lm.out <- lm(y~.,data=df.pc,subset=s)
lm.pred <- predict(lm.out,newdata=df.pc[-s,])
mean((lm.pred-df.pc$y[-s])^2)
[1] 0.0008416416The test-set MSEs are the same!
What happens if we learn a model with just the first two PCs, the ones that account for 99.8% of the data variability?
lm.out <- lm(y~PC1+PC2,data=df.pc,subset=s)
lm.pred <- predict(lm.out,newdata=df.pc[-s,])
mean((lm.pred-df.pc$y[-s])^2)
[1] 0.001437671The test-set MSE increases: there can be/will be a tradeoff between enhanced model interpretability and decreased model predictive ability if we summarily remove PCs
- PC regression learns models with “shifted” predictor variable values: with sufficient sample size, this can markedly impact prediction results, even if the retained PCs represent an overwhelming proportion of the cumulative variance
What happens if we utilize
bestglm?
suppressMessages(library(bestglm))
bg.out <- bestglm(df.pc,IC="BIC")
bg.out$BestModel
Call:
lm(formula = y ~ ., data = data.frame(Xy[, c(bestset[-1], FALSE),
    drop = FALSE], y = y))

Coefficients:
(Intercept)          PC1          PC2          PC3          PC4          PC5
    0.17455      0.00569      0.02354     -0.09395      0.25060     -0.45007
        PC6
   -0.74064
Upshot: the best set of PCs for visualization/intuition-building is not necessarily the best set of PCs for modeling!
Let’s summarize the “best” model
summary(bg.out$BestModel)$coefficients Estimate Std. Error t value Pr(>|t|)
(Intercept) 0.174550826 0.0009369600 186.294847 0.000000e+00
PC1 0.005690051 0.0003872504 14.693466 2.389390e-44
PC2 0.023536423 0.0025977839 9.060193 6.830750e-19
PC3 -0.093945739 0.0118547286 -7.924748 6.147270e-15
PC4 0.250602201 0.0179780474 13.939345 1.901929e-40
PC5 -0.450074996 0.0369510332 -12.180309 6.773436e-32
PC6 -0.740638090 0.0671668890 -11.026833 9.593036e-27We see if we change, e.g., PC2 by 1 unit, the distance will change by 0.024…but how does that change map back to the original variables?
- so while it can be worthwhile to shift to PC coordinates to mitigate multicollinearity, crafting an inferential data story that refers back to the original variables can be difficult (and this would be the reason why we wouldn’t “just do” PC regression all the time!)
Note: this data was shared as a TidyTuesday dataset! TidyTuesday is organized by the Data Science Learning Community is a weekly social data project. Its over-arching goal is to provide real-world datasets so that people can learn to work with data. If you are looking to improve your data visualization skills, the TidyTuesday datasets provide a wonderful opportunity to get your hands dirty! We also recommmend searching the hashtag
#TidyTuesdayon social media platforms (e.g. Bluesky) to gain inspiration and see what visualizations others have produced for the most recent TidyTuesday datasets. Oftentimes, participants share a link to their code, which can be helpful for learning cool data visualization tips and tricks!↩︎When joining data, it’s always a good idea to check what rows didn’t match and why that is.↩︎